<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://metaredux.com/feed.xml" rel="self" type="application/atom+xml" /><link href="https://metaredux.com/" rel="alternate" type="text/html" /><updated>2026-09-11T05:52:11+00:00</updated><id>https://metaredux.com/feed.xml</id><title type="html">Meta Redux</title><subtitle>Writings on programming and open-source by Bozhidar Batsov, creator of RuboCop, CIDER, and Prelude.</subtitle><author><name>Bozhidar Batsov</name></author><entry><title type="html">RuboCop 1.91: The Journey to 2.0 Begins</title><link href="https://metaredux.com/posts/2026/09/11/rubocop-1-91.html" rel="alternate" type="text/html" title="RuboCop 1.91: The Journey to 2.0 Begins" /><published>2026-09-11T05:00:00+00:00</published><updated>2026-09-11T05:00:00+00:00</updated><id>https://metaredux.com/posts/2026/09/11/rubocop-1-91</id><content type="html" xml:base="https://metaredux.com/posts/2026/09/11/rubocop-1-91.html"><![CDATA[<p><a href="https://github.com/rubocop/rubocop/releases/tag/v1.91.0">RuboCop 1.91</a> is out! It has the usual mix of new cops, new options and a
small mountain of bug fixes, but the feature I want to talk about today is a single
flag - <code class="language-plaintext highlighter-rouge">--preview</code>. It’s the first real step on our (long) journey to RuboCop 2.0.</p>

<!--more-->

<h2 id="since-the-beginning-of-time">Since the beginning of time…</h2>

<p>…certain people have been unhappy with RuboCop’s defaults. I wrote almost exactly
that sentence <a href="/posts/2020/03/27/adjusting-rubocop-s-defaults.html">six years ago</a>,
right before RuboCop 1.0, when I ran a survey to work out which of our defaults were
wrong. Some good came out of it - that’s how <code class="language-plaintext highlighter-rouge">Layout/LineLength</code> ended up at 120 -
but a survey has an obvious weakness. It asks people what they prefer, and people
are terrible at reporting what they actually do.</p>

<p>So this time I went looking for evidence instead of opinions. I built
<a href="https://github.com/rubocop/rubocop/pull/15362">a small tool</a> that grabs the 500 most-starred Ruby repos on GitHub,
resolves whatever <code class="language-plaintext highlighter-rouge">.rubocop.yml</code> they ship (following <code class="language-plaintext highlighter-rouge">inherit_from</code> chains and
popular <code class="language-plaintext highlighter-rouge">inherit_gem</code> bases like <code class="language-plaintext highlighter-rouge">standard</code> and <code class="language-plaintext highlighter-rouge">rubocop-rails-omakase</code>), and tallies
what they change about our defaults. 233 of them have a config, and
<a href="https://github.com/rubocop/rubocop/issues/15363">the results</a> were interesting in various ways:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">Style/Documentation</code> is turned off outright by 53% of them. It’s the most disabled
cop by a wide margin.</li>
  <li>Seven of the ten most disabled cops are <code class="language-plaintext highlighter-rouge">Metrics</code> cops.</li>
  <li>Our <code class="language-plaintext highlighter-rouge">Metrics/MethodLength</code> default is 10; the median project that touches it sets
    <ol>
      <li><code class="language-plaintext highlighter-rouge">AbcSize</code> goes from 17 to 28. <code class="language-plaintext highlighter-rouge">ClassLength</code> goes from 100 to 300.</li>
    </ol>
  </li>
  <li>91% of the projects that set <code class="language-plaintext highlighter-rouge">Style/StringLiterals</code> pick <code class="language-plaintext highlighter-rouge">double_quotes</code> - and all
three of the big shared configs people inherit wholesale already default to it.</li>
</ul>

<p><strong>Note:</strong> people write a line of config only when they <em>disagree</em> with us, so happy
users are invisible here. This shows how far opinionated projects drift from us, not
how everyone feels. Evidence, not proof. Still - when a third of the most visible
Ruby projects out there disable a cop, that cop isn’t teaching anyone anything. It’s
just noise people have learned to mute.</p>

<h2 id="knowing-is-the-easy-part">Knowing is the easy part</h2>

<p>Knowing which defaults are “wrong” and being able to <em>change</em> them are two very
different things. We follow SemVer (semi-)religiously, and changing a default - a
cop’s <code class="language-plaintext highlighter-rouge">Enabled</code> state, a <code class="language-plaintext highlighter-rouge">Max</code> threshold, an <code class="language-plaintext highlighter-rouge">EnforcedStyle</code> - is a breaking change
that has to wait for a major release. That’s exactly the promise we made in
<a href="/posts/2020/10/21/rubocop-1-0.html">RuboCop 1.0</a>, and I have no intention of
walking it back.</p>

<p>Same story for a cop that starts reporting a case it used to miss, or corrects one
differently. Those aren’t new cops, so <code class="language-plaintext highlighter-rouge">pending</code> is no help - they change results for
everyone who already has the cop enabled.</p>

<p>Which leaves us with a lovely little trap. Everything interesting piles up in a queue
waiting for a major release; the major release gets scarier the longer the queue
grows; so it gets postponed; so the queue grows some more. You can see where this
ends. In the 1.0 post I wrote that RuboCop 2.0 would “probably arrive in less than 8
years”, and we’re six years in. I’d very much like to beat my own estimate. I really
do!</p>

<h2 id="enter-preview-mode">Enter preview (mode)</h2>

<p><code class="language-plaintext highlighter-rouge">Preview</code> mode is our way out of that trap. It’s an opt-in channel where the next
major release’s behavior lives until that release ships:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">AllCops</span><span class="pi">:</span>
  <span class="na">Preview</span><span class="pi">:</span> <span class="no">true</span>
</code></pre></div></div>

<p>Or, for a single run:</p>

<div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nv">$ </span>rubocop <span class="nt">--preview</span>
</code></pre></div></div>

<p>It gates three kinds of things. A cop’s entry in the default configuration can now
carry a <code class="language-plaintext highlighter-rouge">Preview</code> section holding the defaults it’s expected to adopt in 2.0:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">Style/Documentation</span><span class="pi">:</span>
  <span class="na">Enabled</span><span class="pi">:</span> <span class="no">true</span>
  <span class="na">Preview</span><span class="pi">:</span>
    <span class="na">Enabled</span><span class="pi">:</span> <span class="no">false</span>
</code></pre></div></div>

<p>A cop can also hide an unstable <em>behavior</em> change behind a <code class="language-plaintext highlighter-rouge">preview?</code> check and ship
it in a minor release. And a cop that’s too speculative to even be <code class="language-plaintext highlighter-rouge">pending</code> can ship
as <code class="language-plaintext highlighter-rouge">Enabled: preview</code>. In all three cases your own configuration still wins over the
default one, exactly as it always has.</p>

<p>The line between <code class="language-plaintext highlighter-rouge">preview</code> and <code class="language-plaintext highlighter-rouge">pending</code> is worth keeping straight, as both mean
“not on by default”. When a new cop gets introduced it’s usually <code class="language-plaintext highlighter-rouge">pending</code> (and
sometimes disabled) - a marker for a pending decision (from you or us). If we’re asking you to
help us find out if something is a good idea, it’s <code class="language-plaintext highlighter-rouge">preview</code>.</p>

<p>I know that’s a bit confusing right now and perhaps down the road <code class="language-plaintext highlighter-rouge">preview</code> will
replace <code class="language-plaintext highlighter-rouge">pending</code> completely for simplicity’s sake. That’s to be determined at this
point. Some ideas and thoughts on this front are most welcome!</p>

<p>One thing to be clear about: preview behavior is unstable and can change or be
withdrawn in any release. That’s the whole point. It makes trying something out cheap
for us, and telling us we got it wrong cheap for you.</p>

<p>I’d love to tell you the idea was original, but it wasn’t. It came out of an
afternoon spent looking at how other linters handle this problem, and they had all
landed in much the same place. <a href="https://docs.astral.sh/ruff/preview/">Ruff</a> has had a <code class="language-plaintext highlighter-rouge">preview</code> mode for a while
now - one global switch gating both preview-only rules and changed behavior inside
existing ones - and we copied that model wholesale. <a href="https://doc.rust-lang.org/clippy/lints.html">Clippy</a> parks its
unfinished and contested lints in a <code class="language-plaintext highlighter-rouge">nursery</code> group that stays off until they’ve
earned their keep. Both admit the same thing: if the only way to try something is to
ship it to everyone at once, you’ll never try anything.</p>

<h2 id="whats-in-the-box-today">What’s in the box today</h2>

<p>1.91 ships the mechanism <em>and</em> a first batch of proposed 2.0 defaults, taken straight
from that corpus data. Flip preview on today and you get:</p>

<ul>
  <li>The entire <code class="language-plaintext highlighter-rouge">Metrics</code> department off. Not because measuring complexity is a bad idea,
but because our thresholds are so far off that people disable the cops rather than
argue with them. I’d rather ship no opinion than a bad one.</li>
  <li>Roughly two dozen contested <code class="language-plaintext highlighter-rouge">Style</code>, <code class="language-plaintext highlighter-rouge">Naming</code> and <code class="language-plaintext highlighter-rouge">Layout</code> cops off -
<code class="language-plaintext highlighter-rouge">Style/IfUnlessModifier</code>, <code class="language-plaintext highlighter-rouge">Style/GuardClause</code>, <code class="language-plaintext highlighter-rouge">Style/ClassAndModuleChildren</code>,
<code class="language-plaintext highlighter-rouge">Style/DoubleNegation</code>, <code class="language-plaintext highlighter-rouge">Style/FrozenStringLiteralComment</code>, <code class="language-plaintext highlighter-rouge">Style/BlockDelimiters</code>
and friends. They’re all near the top of the disable leaderboard.</li>
  <li><code class="language-plaintext highlighter-rouge">Style/Documentation</code> off, obviously.</li>
  <li>The community’s <code class="language-plaintext highlighter-rouge">EnforcedStyle</code> wherever it differs from ours: <code class="language-plaintext highlighter-rouge">double_quotes</code> for
<code class="language-plaintext highlighter-rouge">Style/StringLiterals</code>, <code class="language-plaintext highlighter-rouge">brackets</code> for <code class="language-plaintext highlighter-rouge">Style/SymbolArray</code> and <code class="language-plaintext highlighter-rouge">Style/WordArray</code>,
and <code class="language-plaintext highlighter-rouge">consistent</code>/<code class="language-plaintext highlighter-rouge">indented</code>/<code class="language-plaintext highlighter-rouge">with_fixed_indentation</code> across the multiline
indentation family.</li>
  <li><code class="language-plaintext highlighter-rouge">AllCops: FailLevel: warning</code>, so style offenses get reported without failing your
build. More on this one in a moment.</li>
  <li><code class="language-plaintext highlighter-rouge">Exclude</code> merging with the default configuration and with inherited files instead of
replacing them - the fix for <a href="https://github.com/rubocop/rubocop/issues/9325">#9325</a>, one of our oldest configuration
papercuts.</li>
</ul>

<p>That’s 34 cops switched off and 17 defaults adjusted. A start, not a destination.</p>

<h2 id="a-less-prescriptive-rubocop">A less prescriptive RuboCop</h2>

<p>I want RuboCop 2.0 to ship a much smaller and much less prescriptive default
configuration than 1.x does.</p>

<p>This isn’t a new idea for me. Back in the <a href="/posts/2022/04/21/rubocop-turns-10.html">10th anniversary
post</a> I admitted that “we might have gone
overboard at times in our desire to improve Ruby codebases”, and I listed bundling
cops into presets as one of the things I wanted for 2.0, to address “the common
complaint that RuboCop checks for way too many things out of the box”. Four years
later that complaint hasn’t gone anywhere, and now I’ve got the numbers to back it up.</p>

<p>There’s a slightly embarrassing part to this story too. It wasn’t until I was digging
through that data that it hit me how many cops we ship these days. 613. I’ve been
maintaining this project for fourteen years and that number genuinely shocked me.
Sure, I knew it was a lot - I’d just never looked at the figure, and once you have,
it’s hard to unsee. That’s what got me focused on making the default configuration
leaner.</p>

<p>RuboCop grew up as the “enforcement” arm of the <a href="https://rubystyle.guide">Ruby Style Guide</a>, and
for many years “is it in the style guide?” was a good enough answer to “should it be
on by default?”. I still stand firmly behind the style guide. But the tool has
outgrown that framing - that’s an awful lot of opinions to hand someone on their first
day, and the data says most people don’t want most of them. Out of the box RuboCop
should catch real problems and stay out of your way on matters of taste. If you want
the full sermon, you should have to ask for it.</p>

<p>Sure, this sounds a lot like <a href="https://github.com/standardrb/standard">Standard</a>, and I have no problem admitting
they got there before we did. The popularity of Standard and <code class="language-plaintext highlighter-rouge">rubocop-rails-omakase</code>
was the community telling us something, and we took our sweet time listening. The
difference is that RuboCop will stay exactly as configurable as it’s always been. I’m
not taking away any knobs, I’m changing which ones start in the “on” position.<sup id="fnref:1" role="doc-noteref"><a href="#fn:1" class="footnote" rel="footnote">1</a></sup> If
your project loves our current defaults, you’ll be able to keep every last one of them.</p>

<p>Preview isn’t the only thing in motion here, either. The presets work I promised in
that anniversary post is moving again - <a href="https://github.com/rubocop/rubocop/issues/14005">#14005</a> has the discussion and
<a href="https://github.com/rubocop/rubocop/pull/14994">#14994</a> a first prototype - and I see the two as related rather than
competing. Preview asks “is this particular default wrong?”. Presets ask the broader
“how many cops should be running at all?”, by letting you pick a bundle - something
essential, something recommended, the full style guide - instead of arguing over
several hundred separate decisions. And the preview feedback feeds straight into that:
every cop you tell me you don’t miss is a cop that belongs in a stricter tier, and
every one you yell at me about belongs in the baseline. I’d like to land both for 2.0.</p>

<p>The severity work in this release is part of the same push. A cop’s default severity
now comes from its department, so <code class="language-plaintext highlighter-rouge">Security</code> cops report as <code class="language-plaintext highlighter-rouge">warning</code> and <code class="language-plaintext highlighter-rouge">Metrics</code>
cops as <code class="language-plaintext highlighter-rouge">refactor</code>. Combined with the new <code class="language-plaintext highlighter-rouge">AllCops: FailLevel</code> - the configuration
equivalent of <code class="language-plaintext highlighter-rouge">--fail-level</code>, which somehow we never had - you finally get a better
dial than “everything fails the build equally”:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">AllCops</span><span class="pi">:</span>
  <span class="na">FailLevel</span><span class="pi">:</span> <span class="s">warning</span>
</code></pre></div></div>

<p>With that, only <code class="language-plaintext highlighter-rouge">Lint</code> and <code class="language-plaintext highlighter-rouge">Security</code> offenses (plus anything you’ve bumped yourself)
fail the run. Everything else still gets printed, it just doesn’t paint your CI red.</p>

<h2 id="the-rest-of-the-release">The rest of the release</h2>

<p>Preview stole the show, but there’s plenty else in here - and a few of these came out
of that same survey of the competition:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">--diff</code> prints a unified diff of what autocorrection <em>would</em> change, without
touching a single file. This is the CI check I’ve wanted for ages - the build fails
with the patch that would fix it sitting right there in the log, and
<code class="language-plaintext highlighter-rouge">rubocop --diff --format quiet | git apply</code> gets you that patch locally.</li>
  <li><code class="language-plaintext highlighter-rouge">--changed</code> inspects only the files git says changed, defaulting to a diff against
<code class="language-plaintext highlighter-rouge">HEAD</code> (any revision works, and untracked files count). It pairs beautifully with
<code class="language-plaintext highlighter-rouge">--diff</code>.</li>
  <li>There’s a SARIF formatter now, so <code class="language-plaintext highlighter-rouge">rubocop --format sarif --out rubocop.sarif</code> feeds
straight into GitHub code scanning and your offenses show up annotated on the pull
request diff.</li>
  <li><code class="language-plaintext highlighter-rouge">Lint/MisplacedMagicComment</code> is a new cop that flags magic comments Ruby silently
ignores - an <code class="language-plaintext highlighter-rouge"># encoding:</code> comment that isn’t on the first line, a
<code class="language-plaintext highlighter-rouge"># frozen_string_literal: true</code> that drifted below a <code class="language-plaintext highlighter-rouge">require</code>, a magic comment that
pushed a shebang off line one. Quietly doing nothing is the worst failure mode a
magic comment can have.</li>
  <li>Two new directives. <code class="language-plaintext highlighter-rouge"># rubocop:enable-next</code> re-enables a cop for exactly one
statement, with no closing directive to maintain. <code class="language-plaintext highlighter-rouge"># rubocop:next</code> covers the same
statement scope but takes <code class="language-plaintext highlighter-rouge">push</code>-style <code class="language-plaintext highlighter-rouge">+</code>/<code class="language-plaintext highlighter-rouge">-</code> arguments, for the rare case that
needs toggles in both directions at once. <code class="language-plaintext highlighter-rouge">Style/DirectiveScope</code> will convert your
existing pairs to the tighter forms.</li>
  <li><code class="language-plaintext highlighter-rouge">Lint/CopDirectiveSyntax</code> is enabled by default now, so a directive that silently
suppresses nothing gets reported instead of fooling you for years. It absorbed
<code class="language-plaintext highlighter-rouge">Style/DoubleCopDisableDirective</code>, which is gone.</li>
  <li><code class="language-plaintext highlighter-rouge">Style/DisableCopsWithinSourceCodeDirective</code> gained an <code class="language-plaintext highlighter-rouge">AllowedDirectives</code> option, so
you can ban hand-written <code class="language-plaintext highlighter-rouge">disable</code> comments while still letting generated
<code class="language-plaintext highlighter-rouge">rubocop:todo</code> entries through. Its cop lists match department names too now.</li>
  <li>And a mountain of bug fixes - a long parade of infinite loops between cops squashed,
more crashes and bad autocorrections than I care to admit to, and two result cache
bugs, one of which could serve one file’s cached results for another file. The
<a href="https://github.com/rubocop/rubocop/releases/tag/v1.91.0">release notes</a> have the full list.</li>
</ul>

<h2 id="epilogue">Epilogue</h2>

<p>The most useful thing you can do right now is run <code class="language-plaintext highlighter-rouge">rubocop --preview</code> on your codebase
and tell us what you think. Which of those disabled cops do you actually miss? Which
<code class="language-plaintext highlighter-rouge">EnforcedStyle</code> did we get wrong? What did we leave switched on that should have gone?
That’s the whole reason preview exists - I’d much rather find out now than on the day
2.0 ships. <a href="https://github.com/rubocop/rubocop/issues">Open an issue</a>, comment on <a href="https://github.com/rubocop/rubocop/issues/15363">the defaults
discussion</a>, or just yell about it on the internet. I’ll find it.</p>

<p>Big thanks to everyone who contributed to this release! <a href="https://github.com/viralpraxis">viralpraxis</a> and
<a href="https://github.com/Starlexxx">Starlexxx</a> in particular did a huge amount of the bug-fixing this cycle, and Koichi
keeps being Koichi. And thanks to everyone who’s been arguing with our defaults all
these years - turns out you were mostly right.</p>

<p>That’s all I have for you today. Keep hacking!</p>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1" role="doc-endnote">
      <p>Famous last words, I’m well aware. <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Bozhidar Batsov</name></author><category term="posts" /><category term="Ruby" /><category term="RuboCop" /><summary type="html"><![CDATA[RuboCop 1.91 is out! It has the usual mix of new cops, new options and a small mountain of bug fixes, but the feature I want to talk about today is a single flag - --preview. It’s the first real step on our (long) journey to RuboCop 2.0.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://metaredux.com/assets/og-image.png" /><media:content medium="image" url="https://metaredux.com/assets/og-image.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Clojurists Together Update: July and August 2026</title><link href="https://metaredux.com/posts/2026/09/10/clojurists-together-update-july-august-2026.html" rel="alternate" type="text/html" title="Clojurists Together Update: July and August 2026" /><published>2026-09-10T09:30:00+00:00</published><updated>2026-09-10T09:30:00+00:00</updated><id>https://metaredux.com/posts/2026/09/10/clojurists-together-update-july-august-2026</id><content type="html" xml:base="https://metaredux.com/posts/2026/09/10/clojurists-together-update-july-august-2026.html"><![CDATA[<p>Time for another bi-monthly update on the work that <a href="https://www.clojuriststogether.org/">Clojurists Together</a> are funding this year - my
maintenance of <a href="https://nrepl.org">nREPL</a>, <a href="https://cider.mx">CIDER</a> and friends. I published the <a href="/posts/2026/07/05/clojurists-together-update-may-june-2026.html">previous one</a> as a blog post for the first time
and the feedback was good enough that I’ll keep doing it.</p>

<p>Last time I said that I had plucked most of the low-hanging fruit and that the next two months were unlikely to be as productive. Well, I was wrong.
CIDER 2.0 finally shipped, and once it was out the door I used the momentum to sweep through pretty much every corner of the nREPL/CIDER ecosystem.
A few long-neglected projects got proper releases, and nREPL got a couple of brand new implementations in languages I play on the side from time to time.</p>

<!--more-->

<p>The big highlights from my perspective:</p>

<ul>
  <li>CIDER 2.0 (“Terceira”) is out, followed by 2.0.1, and 2.1 is taking shape on master</li>
  <li><a href="https://github.com/clojure-emacs/clj-refactor.el">clj-refactor</a> 4.0 is out</li>
  <li><a href="https://github.com/clojure-emacs/sayid">Sayid</a> went from 0.4 to 0.8 in the span of three weeks</li>
  <li><a href="https://github.com/nrepl/drawbridge">Drawbridge</a>, nREPL’s HTTP transport, got its first meaningful release in years</li>
  <li>nREPL went polyglot: <a href="https://github.com/nrepl/nrepl-beam">nREPL servers for Erlang and Elixir</a> and <a href="https://github.com/nrepl/mezcaml">an OCaml client</a></li>
  <li><a href="https://github.com/clojure-emacs/clj-suitable">clj-suitable</a> 0.7 and 0.8 closed most of the gap between ClojureScript and Clojure completion</li>
  <li>A lot of work landed on nREPL’s master (TLS hardening, URL-based connections, docs) and a new release is right around the corner</li>
</ul>

<p>Below you’ll find more details about the work I did, project by project.</p>

<h2 id="cider">CIDER</h2>

<p><a href="https://github.com/clojure-emacs/cider/releases/tag/v2.0.0">CIDER 2.0 (“Terceira”)</a> landed on July 15, right on the schedule I had
announced in the <a href="/posts/2026/06/30/cider-2-0-is-brewing.html">preview post</a>. For once in my life I was actually on time!
The big themes were covered there and in the <a href="/posts/2026/07/15/cider-2-0.html">release announcement</a> (transient menus, inline macro stepping, call-graph browsers,
source-based find-references, the tracing and tap buffers, rich content in the REPL), so here’s just what changed between
the preview and the final release:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">cider-doctor</code>, which checks your Emacs setup and the active nREPL session for common problems and produces a report you can paste in a bug report</li>
  <li>an <code class="language-plaintext highlighter-rouge">orchard</code> value for <code class="language-plaintext highlighter-rouge">cider-print-fn</code>, selecting cider-nrepl’s much faster <code class="language-plaintext highlighter-rouge">orchard.pp</code> pretty-printer</li>
  <li>SSH tunnels now forward a free local port, so remote REPLs sharing a port no longer collide on localhost</li>
  <li><code class="language-plaintext highlighter-rouge">C-c C-d</code> at the stdin prompt sends end-of-input, and stdin is routed to the exact connection that asked for it</li>
  <li>a long tail of nREPL client fixes: a slow memory leak on the eldoc/completion path, <code class="language-plaintext highlighter-rouge">nrepl-dict-merge</code> mutating a shared literal, notifications treated as format strings</li>
</ul>

<p><a href="https://github.com/clojure-emacs/cider/releases/tag/v2.0.1">CIDER 2.0.1</a> followed a week later with fixes for the problems early
adopters ran into: evaluation in a dependency’s source buffer erroring with “No linked CIDER sessions” (in several variants),
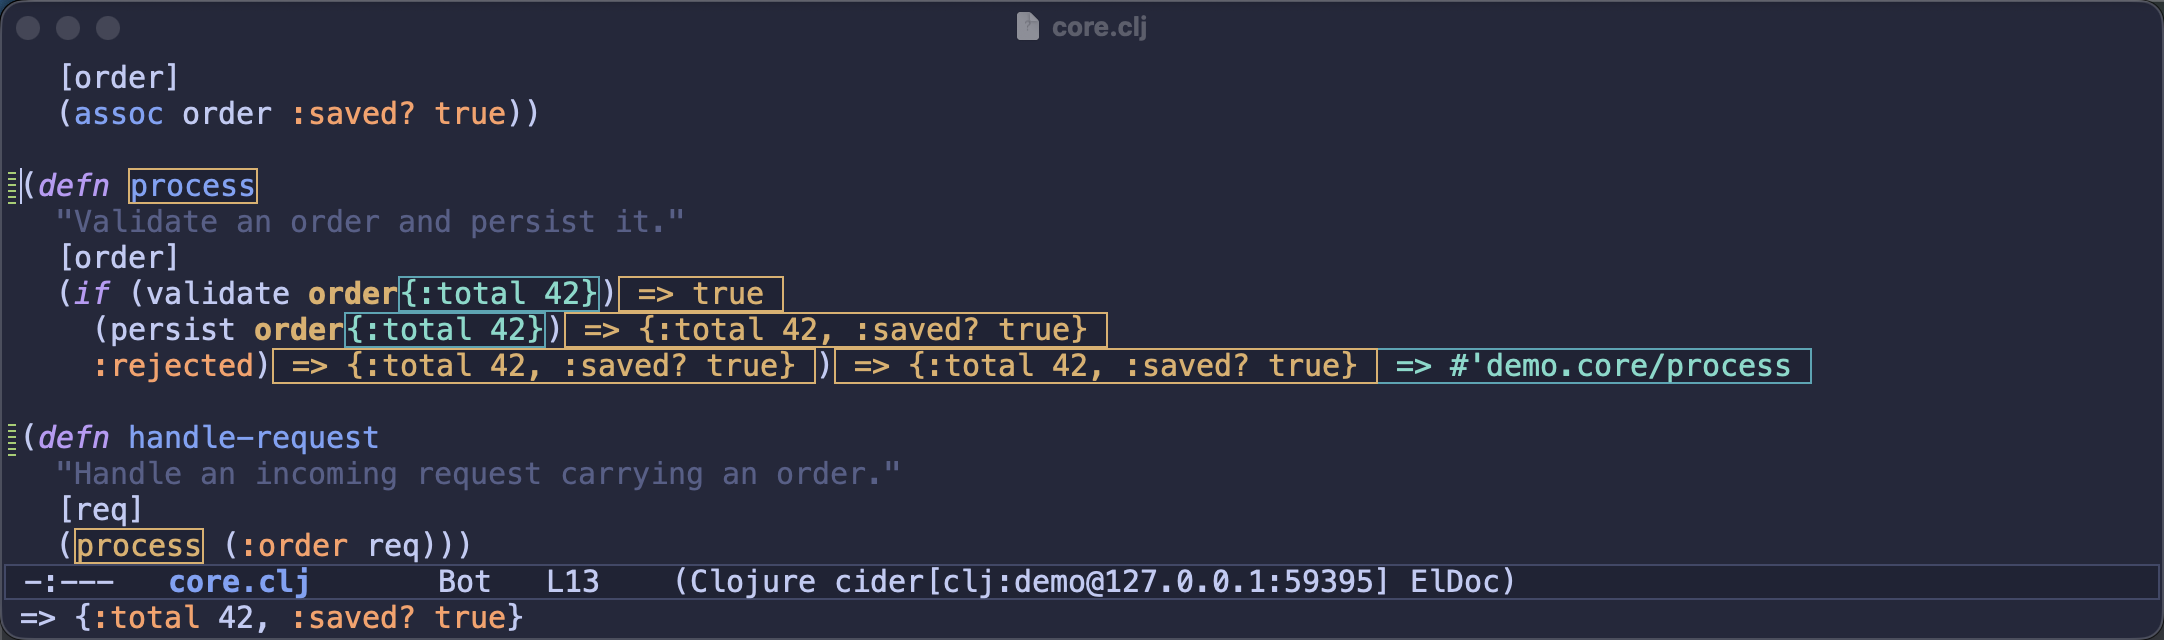
<code class="language-plaintext highlighter-rouge">cider-enlighten-mode</code> never lighting anything up (a 1.22 regression), the macroexpansion commands refusing to expand
<code class="language-plaintext highlighter-rouge">let</code>/<code class="language-plaintext highlighter-rouge">fn</code>/<code class="language-plaintext highlighter-rouge">loop</code>, and <code class="language-plaintext highlighter-rouge">load-file</code> potentially freezing Emacs on a huge result. Nothing dramatic, but I’m glad people were quick to report those.</p>

<p>After that master (the future CIDER 2.1) kept moving at a steady pace. A few of the things that landed there:</p>

<ul>
  <li>CIDER’s dynamic font-locking (REPL-defined macros, functions, deprecated/instrumented/traced symbols) now works better in <code class="language-plaintext highlighter-rouge">clojure-ts-mode</code> buffers via tree-sitter. Previously it worked “officially” only under <code class="language-plaintext highlighter-rouge">clojure-mode</code>. The debugging reader tags are highlighted there too.</li>
  <li>A new <code class="language-plaintext highlighter-rouge">cider-preferred-clojure-mode</code> controls which mode CIDER uses to font-lock the code it renders - REPL results, doc examples, overlays and its own display buffers. <code class="language-plaintext highlighter-rouge">clojure-ts-mode</code> is finally a first-class citizen in CIDER.</li>
  <li>Symbol prompts can go through <code class="language-plaintext highlighter-rouge">completing-read</code> (so Vertico/Ivy/Helm kick in) and completion annotations render as an aligned type/namespace column in Corfu, Vertico and the built-in <code class="language-plaintext highlighter-rouge">*Completions*</code>. More on this in <a href="/posts/2026/07/25/modernizing-cider-completion.html">Modernizing CIDER’s Completion</a>.</li>
  <li>Connecting got smarter. Container-published nREPL ports are resolved for <code class="language-plaintext highlighter-rouge">/docker:</code> and <code class="language-plaintext highlighter-rouge">/podman:</code> buffers, <code class="language-plaintext highlighter-rouge">lein trampoline</code> REPLs are detected, <code class="language-plaintext highlighter-rouge">.nrepl-port</code> files are no longer discarded on systems without <code class="language-plaintext highlighter-rouge">lsof</code>, and there’s a new <a href="https://docs.cider.mx/cider/basics/up_and_running.html#how-cider-finds-ports">“How CIDER Finds Ports”</a> section in the manual.</li>
  <li>Every form command got an “at point” variant (inspect, pprint, macroexpand, format, insert in REPL), there’s a <code class="language-plaintext highlighter-rouge">cider-inspect-menu</code> listing every way to start an inspection, and the contents of <code class="language-plaintext highlighter-rouge">comment</code> forms are treated as top level by the whole defun command family.</li>
  <li>Stray output from long-lived background processes (say, a <code class="language-plaintext highlighter-rouge">core.async</code> go-loop still printing under a finished eval’s id) is now routed to the REPL instead of being dropped with a warning.</li>
</ul>

<p>One more thing. I shipped “smarter form targeting” on master - the evaluation commands resolving the form from where the cursor
actually is, rather than the form before it - <a href="/posts/2026/08/26/smarter-form-targeting-is-coming-to-cider.html">wrote about it</a>,
got a lot of feedback, and <a href="/posts/2026/08/29/smarter-form-targeting-is-not-coming-to-cider.html">reverted it</a> a few days later.
CIDER 2.1 will keep the classic Emacs semantics. Fifteen years in, the existing behaviour is the contract, not an implementation detail I get to tidy up.
The detour wasn’t wasted, though: it surfaced a bug where the text of a line comment was treated as code,
and the “at point” family of commands is a direct result of it.</p>

<h2 id="cider-nrepl">cider-nrepl</h2>

<p>Three <a href="https://github.com/clojure-emacs/cider-nrepl">cider-nrepl</a> releases in July, wrapping up the tools.deps migration and driving the CIDER 2.0 launch:</p>

<ul>
  <li><a href="https://github.com/clojure-emacs/cider-nrepl/releases/tag/v0.62.0">cider-nrepl 0.62.0</a> finalized the Leiningen to tools.deps migration, simplified deferred middleware loading, documented the op response keys (with a test verifying the descriptor contract) and shipped the hardened content-type and slurp middleware that made rich content safe to enable by default.</li>
  <li><a href="https://github.com/clojure-emacs/cider-nrepl/releases/tag/v0.62.1">cider-nrepl 0.62.1</a> fixed a whole cluster of debugger bugs. Record literals no longer get downgraded to plain maps by instrumentation, <code class="language-plaintext highlighter-rouge">deftype</code>/<code class="language-plaintext highlighter-rouge">defrecord</code> method bodies are skipped (goodbye <code class="language-plaintext highlighter-rouge">Unable to resolve symbol: STATE__</code>), and enlightening <code class="language-plaintext highlighter-rouge">deftest</code> bodies works again.</li>
  <li><a href="https://github.com/clojure-emacs/cider-nrepl/releases/tag/v0.62.2">cider-nrepl 0.62.2</a> pruned trace and tap subscriptions with dead transports (a dead subscriber used to break every traced evaluation), stopped the debugger from shadowing enlighten’s evaluator, brought the docs back in sync with the code and added a <a href="https://docs.cider.mx/cider-nrepl/tool-authors/index.html">section for tool authors</a>.</li>
</ul>

<h2 id="orchard">Orchard</h2>

<p><a href="https://github.com/clojure-emacs/orchard/releases/tag/v0.44.0">Orchard 0.44.0</a> shipped on July 4, mostly thanks to Sashko’s inspector work (a <code class="language-plaintext highlighter-rouge">replace</code> command,
truncated table columns, <code class="language-plaintext highlighter-rouge">ARef</code> contents rendered fully). My part was a round of tests for the less covered namespaces and, later on master,
a fix for <code class="language-plaintext highlighter-rouge">orchard.print</code> ignoring custom <code class="language-plaintext highlighter-rouge">print-method</code> implementations for records and collections. Thanks, Sashko!</p>

<h2 id="clj-refactor-40">clj-refactor 4.0</h2>

<p><a href="https://github.com/clojure-emacs/clj-refactor.el/releases/tag/v4.0.0">clj-refactor.el 4.0</a> is the release I had been promising for a few cycles.
It requires Emacs 28.1+ and CIDER 2.0+, and it’s a big one:</p>

<ul>
  <li>project-wide refactorings (rename symbol, change signature, inline symbol) now show a diff preview before touching disk, and <code class="language-plaintext highlighter-rouge">cljr-undo-last-refactoring</code> reverts the last one in a single step</li>
  <li>the slow refactorings run asynchronously, so Emacs no longer freezes while the middleware analyzes the project</li>
  <li><code class="language-plaintext highlighter-rouge">cljr-change-function-signature</code> can add and remove parameters and handles multi-arity functions</li>
  <li>a <code class="language-plaintext highlighter-rouge">clj-refactor-menu</code> transient replaces the hydra menus, and the <code class="language-plaintext highlighter-rouge">multiple-cursors</code>, <code class="language-plaintext highlighter-rouge">hydra</code> and <code class="language-plaintext highlighter-rouge">inflections</code> dependencies are gone</li>
  <li>many commands degrade gracefully without a REPL (<code class="language-plaintext highlighter-rouge">cljr-clean-ns</code>, <code class="language-plaintext highlighter-rouge">cljr-slash</code>, <code class="language-plaintext highlighter-rouge">cljr-add-missing-libspec</code>, <code class="language-plaintext highlighter-rouge">cljr-remove-let</code>, <code class="language-plaintext highlighter-rouge">cljr-promote-function</code>)</li>
  <li><code class="language-plaintext highlighter-rouge">cljr-slash</code> can add and hotload a missing library, artifact lists are cached, and the namespaced refactor-nrepl ops are used when available</li>
</ul>

<p>I still think the long-term home for the most useful bits is CIDER and clojure-mode, but at least the project is in good shape while I figure that out.
There’s a bit more in the <a href="/posts/2026/07/16/clj-refactor-4-0.html">release post</a>.</p>

<h2 id="clj-suitable">clj-suitable</h2>

<p><a href="https://github.com/clojure-emacs/clj-suitable">clj-suitable</a>, the ClojureScript completion backend, was another project that had been coasting for years:</p>

<ul>
  <li><a href="https://github.com/clojure-emacs/clj-suitable/releases/tag/0.7.0">clj-suitable 0.7.0</a> adapted to Piggieback 0.7’s delegating repl-env, modernized every dependency, replaced the Leiningen build with tools.build, moved CI to GitHub Actions and added a shadow-cljs integration test over a real Node runtime.</li>
  <li><a href="https://github.com/clojure-emacs/clj-suitable/releases/tag/0.8.0">clj-suitable 0.8.0</a> brought the static completion much closer to compliment: fuzzy matching (<code class="language-plaintext highlighter-rouge">pr-fn</code> completes <code class="language-plaintext highlighter-rouge">print-function</code>), compliment-style ranking, completion of local bindings (destructuring included) and of referred vars inside <code class="language-plaintext highlighter-rouge">:refer</code> vectors. It also fixed the REPL’s <code class="language-plaintext highlighter-rouge">*1</code>/<code class="language-plaintext highlighter-rouge">*2</code>/<code class="language-plaintext highlighter-rouge">*3</code> getting clobbered by completions and a few long-standing shadow-cljs and Node.js issues.</li>
</ul>

<p>ClojureScript users - I’d love to hear how the new completion feels in practice.</p>

<h2 id="sayid">Sayid</h2>

<p>The <a href="/posts/2026/07/01/sayid-redux.html">Sayid revival</a> continued at a brisk pace, with five releases between July 1 and July 17:</p>

<ul>
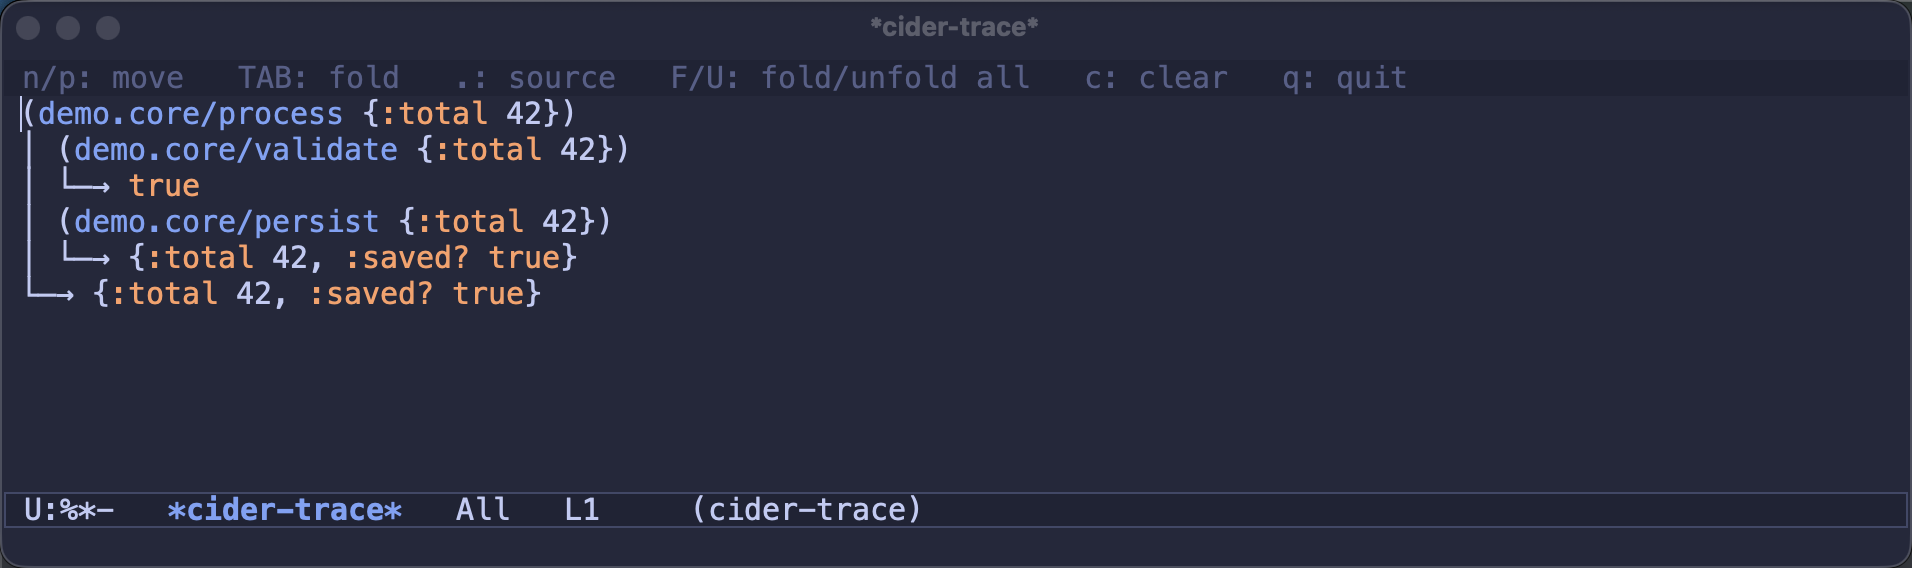
  <li><a href="https://github.com/clojure-emacs/sayid/blob/master/CHANGELOG.md#040---2026-07-01">Sayid 0.4.0</a> dropped the <code class="language-plaintext highlighter-rouge">com.billpiel</code> namespace prefix, added data-returning variants of the workspace and query ops, and introduced a client-rendered, foldable tree view of the recorded call tree built on CIDER’s <code class="language-plaintext highlighter-rouge">cider-tree-view</code>.</li>
  <li><a href="https://github.com/clojure-emacs/sayid/blob/master/CHANGELOG.md#050---2026-07-01">Sayid 0.5.0</a> made recording bounded: a record limit, per-function limits, sampling, a max trace depth and bounded printing. Tracing a namespace under a test suite can’t eat all your memory anymore.</li>
  <li><a href="https://github.com/clojure-emacs/sayid/blob/master/CHANGELOG.md#060---2026-07-08">Sayid 0.6.0</a> rebuilt inner tracing on <code class="language-plaintext highlighter-rouge">tools.analyzer.jvm</code>, replacing the fragile source-rewriting instrumenter.</li>
  <li><a href="https://github.com/clojure-emacs/sayid/blob/master/CHANGELOG.md#070---2026-07-10">Sayid 0.7.0</a> added <code class="language-plaintext highlighter-rouge">sayid.data</code> (the recorded call tree as plain data, with <code class="language-plaintext highlighter-rouge">tap&gt;</code> integration for Portal and friends) and <code class="language-plaintext highlighter-rouge">sayid.golden</code>, a golden-trace testing helper.</li>
  <li><a href="https://github.com/clojure-emacs/sayid/blob/master/CHANGELOG.md#080---2026-07-17">Sayid 0.8.0</a> focused on the experience: a <code class="language-plaintext highlighter-rouge">sayid-menu</code> transient, plain-language feedback from the trace commands, getting-started hints in empty views, and a fix for the inspector integration that had been broken for years.</li>
</ul>

<p>I wrote a bit more about the last one <a href="/posts/2026/07/18/sayid-0-8.html">here</a>. Not bad for a project that was completely dead in June, right?</p>

<h2 id="drawbridge">Drawbridge</h2>

<p>Drawbridge is nREPL’s HTTP transport, created by Chas Emerick in 2012 and “technically maintained” ever since. I finally gave it the attention it needed:</p>

<ul>
  <li><a href="https://github.com/nrepl/drawbridge/releases/tag/v0.3.1">Drawbridge 0.3.1</a> updated the dependencies (nREPL 1.7, Ring 1.15) and throttled client polling so it stops flooding servers with GET requests.</li>
  <li><a href="https://github.com/nrepl/drawbridge/releases/tag/v0.4.0">Drawbridge 0.4.0</a> is the interesting one. It adds <code class="language-plaintext highlighter-rouge">drawbridge.bridge</code>, a local nREPL socket server that relays to a remote Drawbridge endpoint, so any socket-based client (CIDER, Calva, rebel-readline) can now talk to Drawbridge. There’s also a WebSocket transport with server push instead of long-polling, bearer-token authentication via <code class="language-plaintext highlighter-rouge">secure-ring-handler</code> (which refuses to run unauthenticated unless you insist), and a <code class="language-plaintext highlighter-rouge">deps.edn</code>, so it’s usable as a git dependency.</li>
</ul>

<p>The full story is in <a href="/posts/2026/07/14/lowering-the-drawbridge.html">Lowering the Drawbridge</a>.</p>

<h2 id="nrepl">nREPL</h2>

<p>No nREPL release this cycle, but master is shaping up nicely for 1.8:</p>

<ul>
  <li>the built-in command-line client can connect using a URL, including the <code class="language-plaintext highlighter-rouge">nrepls://</code> and <code class="language-plaintext highlighter-rouge">nrepl+unix:</code> URLs that TLS and filesystem-socket servers advertise, and <code class="language-plaintext highlighter-rouge">http(s)://</code> when Drawbridge is on the classpath</li>
  <li>TLS hardening: descriptive errors for invalid key material, Ed25519 keys, tolerating a swapped certificate order, and a <a href="https://nrepl.org/nrepl/usage/tls.html">documented security model</a></li>
  <li>the built-in client sends input to the server as raw text, so reader typos, auto-resolved keywords and custom tagged literals no longer crash it</li>
  <li>stdin fixes: EOF arriving behind buffered input is reported properly, and a race between the stdin consumer and producer is gone</li>
  <li><code class="language-plaintext highlighter-rouge">nrepl.spec</code> finally matches what <code class="language-plaintext highlighter-rouge">describe</code> and <code class="language-plaintext highlighter-rouge">ls-sessions</code> actually send</li>
  <li>a pile of documentation debt cleared (<code class="language-plaintext highlighter-rouge">lookup</code> return values, the <code class="language-plaintext highlighter-rouge">session-closed</code> status, the <code class="language-plaintext highlighter-rouge">-f</code>/<code class="language-plaintext highlighter-rouge">--repl-fn</code> option, <a href="https://nrepl.org/nrepl/building_middleware.html">middleware best practices</a>) and a CI check keeping <code class="language-plaintext highlighter-rouge">ops.adoc</code> in sync with the descriptors</li>
  <li>Clojure 1.10 is the new minimum and <code class="language-plaintext highlighter-rouge">nrepl.misc/requiring-resolve</code> is gone in favour of the core one</li>
</ul>

<p>The nrepl.org site also picked up links to several new clients and servers (Nautilos, nREPL.hx for Helix, Janet and Steel Scheme servers).
The nREPL family keeps growing, which makes me happy every single time.</p>

<h2 id="nrepl-on-the-beam">nREPL on the BEAM</h2>

<p><a href="https://github.com/nrepl/nrepl-beam">nrepl-beam</a> is a brand new project I started in July, mostly because I wanted to see how well the nREPL spec holds up
when implemented from scratch outside the JVM. It’s home to:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">dialtone</code>, an nREPL server for Erlang (and a server core for the whole BEAM)</li>
  <li><code class="language-plaintext highlighter-rouge">repartee</code>, the Elixir server built on top of it</li>
  <li><code class="language-plaintext highlighter-rouge">chaser</code>, a terminal nREPL client that works with any nREPL server</li>
</ul>

<p><a href="https://github.com/nrepl/nrepl-beam/releases/tag/v0.1.0">nrepl-beam 0.1.0</a> shipped on July 14. Both servers implement the full op set (eval with streamed output, sessions, interrupts, stdin, load-file, completions, lookup)
and pass <a href="https://github.com/nrepl/neat">neat</a>’s cross-implementation integration suite alongside Clojure, Babashka and Basilisp.
Writing them was a good test of the spec, and it produced a few of the documentation fixes listed above. Turns out that the best way to find holes in a spec is to implement it in a language you barely know.</p>

<h2 id="mezcaml">mezcaml</h2>

<p>In the same spirit, <a href="https://github.com/nrepl/mezcaml">mezcaml</a> is a minimal nREPL client for OCaml: a small client library plus a command-line REPL,
working against any nREPL server regardless of the language on the other end. No release yet, but the core protocol works, it reads whole forms,
and it has server-driven completion. Nothing serious - it was a fun way to combine my recent OCaml hacking with nREPL.</p>

<h2 id="clojure-mode-clojure-ts-mode-and-mranderson">clojure-mode, clojure-ts-mode and MrAnderson</h2>

<p>Smaller things: the <code class="language-plaintext highlighter-rouge">#_</code> toggle commands in clojure-mode were renamed to <code class="language-plaintext highlighter-rouge">clojure-toggle-discard</code> and friends (matching Clojure’s own terminology, old names kept as aliases),
both modes got a <code class="language-plaintext highlighter-rouge">:to-have-face</code> matcher for font-lock tests, and clojure-ts-mode now checks the indentation of its sources on CI.</p>

<p><a href="https://github.com/benedekfazekas/mranderson/releases/tag/v0.7.1">MrAnderson 0.7.1</a> added a command-line interface, so it can be run without Leiningen,
and reworked its downstream integration tests against cider-nrepl and refactor-nrepl, which had silently stopped exercising local changes. Oops.</p>

<h2 id="blog-posts">Blog posts</h2>

<p>I wrote a lot this summer, mostly a series on the notable changes in CIDER 2.0:</p>

<ul>
  <li><a href="/posts/2026/07/14/lowering-the-drawbridge.html">Lowering the Drawbridge</a></li>
  <li><a href="/posts/2026/07/15/cider-2-0.html">CIDER 2.0: Sky is the Limit</a></li>
  <li><a href="/posts/2026/07/16/clj-refactor-4-0.html">clj-refactor.el 4.0</a></li>
  <li><a href="/posts/2026/07/16/simplifying-session-management-in-cider.html">Simplifying Session Management in CIDER</a></li>
  <li><a href="/posts/2026/07/17/stepping-through-macros-in-cider.html">Stepping Through Macros in CIDER</a></li>
  <li><a href="/posts/2026/07/18/sayid-0-8.html">Sayid 0.8</a></li>
  <li><a href="/posts/2026/07/20/clj-suitable-0-8-0.html">clj-suitable 0.8.0: Closing the Gap with Compliment</a></li>
  <li><a href="/posts/2026/07/23/making-cider-more-discoverable.html">Making CIDER More Discoverable</a></li>
  <li><a href="/posts/2026/07/25/modernizing-cider-completion.html">Modernizing CIDER’s Completion</a></li>
  <li><a href="/posts/2026/07/27/closing-the-find-usages-gap-in-cider.html">Closing the Find-Usages Gap in CIDER</a></li>
  <li><a href="/posts/2026/07/28/sharpening-ciders-debugging-tools.html">Sharpening CIDER’s Debugging Tools</a></li>
  <li><a href="/posts/2026/07/29/leveling-up-ciders-clojurescript-support.html">Leveling Up CIDER’s ClojureScript Support</a></li>
  <li><a href="/posts/2026/08/26/smarter-form-targeting-is-coming-to-cider.html">Smarter Form Targeting Is Coming to CIDER</a></li>
  <li><a href="/posts/2026/08/29/smarter-form-targeting-is-not-coming-to-cider.html">Smarter Form Targeting Is Not Coming to CIDER</a></li>
</ul>

<h2 id="epilogue">Epilogue</h2>

<p>Big thanks to Clojurists Together, Nubank and the other organizations and people supporting my Clojure OSS work! None of this would have happened without you. You rock!</p>

<p>As for what’s next - CIDER 2.1 is the obvious milestone, and it’s mostly a matter of letting the clojure-ts-mode integration settle.
After that I’d like to cut nREPL 1.8 with the TLS and URL work, and get mezcaml and the BEAM servers to a point where they are useful
to someone other than me. I won’t make any predictions about productivity this time around. Clearly I’m bad at those.</p>

<p>Keep hacking!</p>]]></content><author><name>Bozhidar Batsov</name></author><category term="posts" /><category term="Clojure" /><category term="nREPL" /><category term="CIDER" /><category term="OSS" /><summary type="html"><![CDATA[Time for another bi-monthly update on the work that Clojurists Together are funding this year - my maintenance of nREPL, CIDER and friends. I published the previous one as a blog post for the first time and the feedback was good enough that I’ll keep doing it. Last time I said that I had plucked most of the low-hanging fruit and that the next two months were unlikely to be as productive. Well, I was wrong. CIDER 2.0 finally shipped, and once it was out the door I used the momentum to sweep through pretty much every corner of the nREPL/CIDER ecosystem. A few long-neglected projects got proper releases, and nREPL got a couple of brand new implementations in languages I play on the side from time to time.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://metaredux.com/assets/og-image.png" /><media:content medium="image" url="https://metaredux.com/assets/og-image.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Smarter Form Targeting Is Not Coming to CIDER</title><link href="https://metaredux.com/posts/2026/08/29/smarter-form-targeting-is-not-coming-to-cider.html" rel="alternate" type="text/html" title="Smarter Form Targeting Is Not Coming to CIDER" /><published>2026-08-29T06:37:00+00:00</published><updated>2026-08-29T06:37:00+00:00</updated><id>https://metaredux.com/posts/2026/08/29/smarter-form-targeting-is-not-coming-to-cider</id><content type="html" xml:base="https://metaredux.com/posts/2026/08/29/smarter-form-targeting-is-not-coming-to-cider.html"><![CDATA[<p>A couple of days ago I wrote that <a href="/posts/2026/08/26/smarter-form-targeting-is-coming-to-cider.html">smarter form targeting was coming to CIDER</a>,
and I ended that post by asking whether I’d got the resolution rules right and
whether anything still surprised people. I got an answer. CIDER 2.1 will ship
with the classic behaviour intact.</p>

<!--more-->

<p>This is not a sad story, though. The detour turned up a bug that was quietly
mangling people’s comments, and CIDER came out of it better than it went in.</p>

<h2 id="what-i-was-actually-after">What I was actually after</h2>

<p>The targeting change wasn’t really about cursor positions. What I wanted was
for <em>every</em> CIDER command that operates on a form to behave the same way,
without adding yet another command to get there. CIDER has an enormous surface
of evaluation commands, and every “at point” variant I could have added would
have made that worse. If the existing commands simply resolved the form you
meant, newcomers would have had fewer commands to learn, not more.</p>

<p>That was the bet: consistency by redefinition rather than by addition. In
hindsight it was the wrong bet for a project this old. Fifteen years in, the
existing behaviour isn’t an implementation detail I get to tidy up - it’s
the contract. And as it turned out, the redefinition wasn’t nearly as
transparent as I’d convinced myself it was.</p>

<h2 id="the-feedback">The feedback</h2>

<p>Several users, including CIDER’s co-maintainer Sashko Yakushev, voiced
concerns and flagged issues I’d overlooked while playing with this initially.
The most important one: inspection is just another flavour of evaluation, and
people inspect bare symbols constantly. If it got the same treatment, the
disruption would be real enough to run a fork over.</p>

<p>My instinct was that this was an edge case, so I measured it instead of
arguing. Across every cursor position in a buffer, only three rules actually
differ, and the flagship flow - type a form, hit <code class="language-plaintext highlighter-rouge">C-x C-e</code> - is identical
under both. Two of those three were fine. The third was this one:</p>

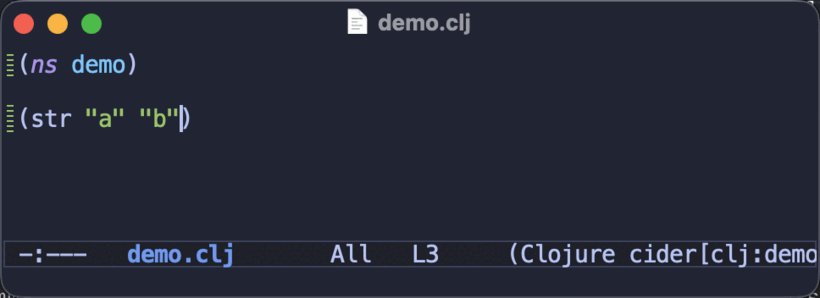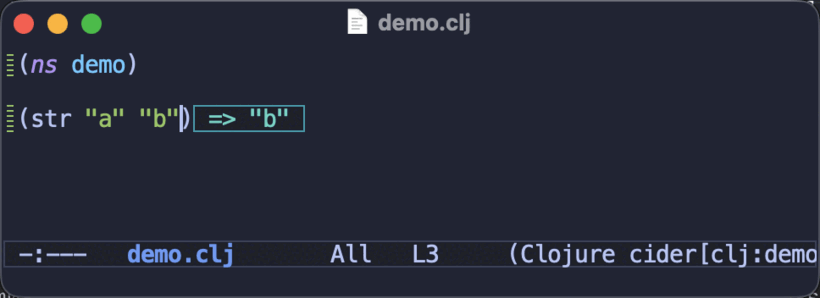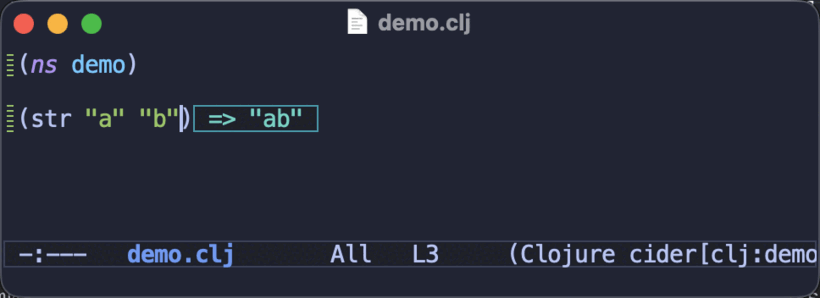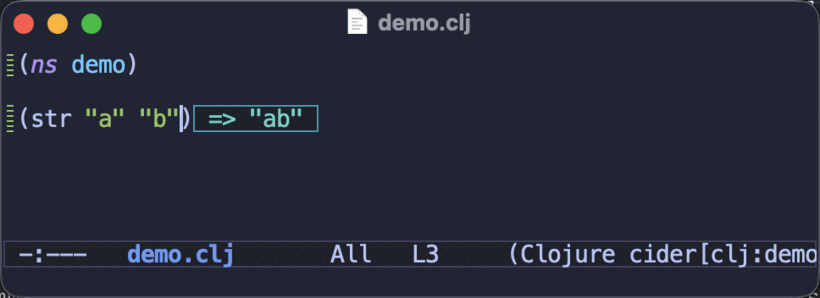
<p><img src="/assets/images/cider-closing-paren.gif" alt="Cursor on a closing paren: the classic rules evaluate the last form inside, smart targeting evaluates the whole enclosing call" /></p>

<p>The cursor doesn’t move between those two evaluations. That’s the same
position, twice, and the answers differ - <code class="language-plaintext highlighter-rouge">"b"</code> under the classic rules,
<code class="language-plaintext highlighter-rouge">"ab"</code> under the new ones.</p>

<p>I’d filed “cursor on a closing paren” as an oddity nobody hits deliberately.
But think about when you land there: you finish typing the last thing inside
a form, and the cursor is now sitting on the <code class="language-plaintext highlighter-rouge">)</code>. For someone inspecting
symbols all day, that fires constantly. And the classic answer isn’t
arbitrary either - as Sashko put it, the rule of thumb is “whatever
<code class="language-plaintext highlighter-rouge">paredit-backward</code> jumps back to”, which is a better description of the
tradition than anything I’d written down.</p>

<h2 id="why-the-tradition-exists-in-the-first-place">Why the tradition exists in the first place</h2>

<p>Here’s the part I under-weighted, and it’s worth spelling out for anyone who
finds “the form <em>before</em> the cursor” arbitrary.</p>

<p>Emacs form navigation overwhelmingly leaves the cursor <em>after</em> a form.
<code class="language-plaintext highlighter-rouge">C-M-f</code> (<code class="language-plaintext highlighter-rouge">forward-sexp</code>) moves over the next form and stops just past its
closing delimiter. <code class="language-plaintext highlighter-rouge">C-M-e</code> (<code class="language-plaintext highlighter-rouge">end-of-defun</code>) leaves you after the whole
top-level form. <code class="language-plaintext highlighter-rouge">C-M-n</code> (<code class="language-plaintext highlighter-rouge">forward-list</code>) does the same for the enclosing
list. Paredit’s <code class="language-plaintext highlighter-rouge">paredit-forward</code> behaves the same way, and so does typing:
finish a form and the cursor is, by definition, right after it.</p>

<p>So “evaluate the preceding form” isn’t a quirk - it <em>composes</em> with how you
already move around. Navigate forward over a form, evaluate it. Type a form,
evaluate it. The cursor is already in the right place, every time.</p>

<p>Getting <em>onto</em> a form instead takes deliberate effort: <code class="language-plaintext highlighter-rouge">C-M-b</code>
(<code class="language-plaintext highlighter-rouge">backward-sexp</code>), <code class="language-plaintext highlighter-rouge">C-M-a</code> (<code class="language-plaintext highlighter-rouge">beginning-of-defun</code>), <code class="language-plaintext highlighter-rouge">paredit-backward</code>, or a
jump package like <code class="language-plaintext highlighter-rouge">avy</code>. All perfectly good tools, but you have to reach for
them - unless you’re clicking around with a mouse, in which case the cursor
lands wherever you pointed and “the form before the cursor” genuinely is
useless. Which, I suspect, is exactly the workflow difference behind this
whole argument.</p>

<h2 id="what-cider-got-instead">What CIDER got instead</h2>

<p>The half of the idea that was never controversial is still there, as commands
you opt into rather than a new meaning for keys you already use. Every
operation now has an “at point” variant, not just eval and tap:
<code class="language-plaintext highlighter-rouge">cider-inspect-sexp-at-point</code>, <code class="language-plaintext highlighter-rouge">cider-pprint-eval-sexp-at-point</code>,
<code class="language-plaintext highlighter-rouge">cider-macroexpand-1-at-point</code>, <code class="language-plaintext highlighter-rouge">cider-macroexpand-all-at-point</code>,
<code class="language-plaintext highlighter-rouge">cider-format-edn-sexp-at-point</code>, <code class="language-plaintext highlighter-rouge">cider-insert-sexp-at-point-in-repl</code>.</p>

<p>Three ways to say which form you mean, and now every command supports all of
them:</p>

<p><img src="/assets/images/cider-form-selection.gif" alt="The same expression evaluated three ways: the preceding form, the form at the cursor, and the enclosing top-level form" /></p>

<p>The at-point commands fall back to the preceding form when there’s nothing to
point at, so they’re drop-in replacements rather than a separate mode of
working. Which means anyone who wanted smart targeting can simply have it:</p>

<div class="language-emacs-lisp highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">(</span><span class="nv">with-eval-after-load</span> <span class="ss">'cider-mode</span>
  <span class="p">(</span><span class="nv">define-key</span> <span class="nv">cider-mode-map</span> <span class="p">(</span><span class="nv">kbd</span> <span class="s">"C-x C-e"</span><span class="p">)</span> <span class="nf">#'</span><span class="nv">cider-eval-sexp-at-point</span><span class="p">)</span>
  <span class="p">(</span><span class="nv">define-key</span> <span class="nv">cider-mode-map</span> <span class="p">(</span><span class="nv">kbd</span> <span class="s">"C-c C-e"</span><span class="p">)</span> <span class="nf">#'</span><span class="nv">cider-eval-sexp-at-point</span><span class="p">))</span>
</code></pre></div></div>

<p>Two lines, no hidden mode, and everyone else’s fingers keep working. This is
what I should have shipped in the first place, and it’s what the
<a href="https://docs.cider.mx/cider/usage/code_evaluation.html">manual</a> now
recommends. Yes, it’s more commands than I wanted. It’s also the version that
doesn’t break anyone.</p>

<p>Macroexpansion is the one place a bit of cleverness survived on its own
merits, because an expansion needs a call form. Stand on a bare symbol and
<code class="language-plaintext highlighter-rouge">cider-macroexpand-1-at-point</code> widens to the call around it, since expanding a
lone symbol is never what anyone meant.</p>

<h2 id="the-bug-at-the-bottom-of-the-hole">The bug at the bottom of the hole</h2>

<p>While unifying the plumbing I found this, which is much worse than anything
form targeting was ever guilty of. Put the cursor at the end of a comment:</p>

<div class="language-clojure highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">(</span><span class="k">defn</span><span class="w"> </span><span class="n">foo</span><span class="w"> </span><span class="p">[])</span><span class="w">
</span><span class="c1">;; a comment|</span><span class="w">
</span></code></pre></div></div>

<p>CIDER answered <code class="language-plaintext highlighter-rouge">comment</code>. Not the <code class="language-plaintext highlighter-rouge">(comment ...)</code> form - the <em>word</em>, lifted
out of your prose, because sexp motion has no notion of comments once the
cursor is inside one and happily reads the words as symbols.</p>

<p>For evaluation that produced a puzzling error. For the in-place macroexpansion
commands, which <em>replace</em> the region they resolved, it did this:</p>

<div class="language-clojure highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1">;; a comment          -&gt;   ;; a EXPANDED&lt;comment&gt;</span><span class="w">
</span><span class="p">(</span><span class="nb">+</span><span class="w"> </span><span class="mi">1</span><span class="w"> </span><span class="mi">2</span><span class="p">)</span><span class="w"> </span><span class="c1">; hey         -&gt;   (+ 1 2)          ; EXPANDED&lt;hey&gt;</span><span class="w">
</span></code></pre></div></div>

<p>It rewrote the comment. That bug has been in CIDER for years, and I only found
it because I went looking at the primitives while cleaning up after myself.</p>

<p>Then I checked the neighbours, and this is my favourite part of the whole
episode: <strong>SLIME, SLY and Emacs Lisp itself all still do this.</strong> Both Lisp
environments use a bare <code class="language-plaintext highlighter-rouge">backward-sexp</code>, and if you put the cursor after
<code class="language-plaintext highlighter-rouge">(+ 1 2) ; hey</code> in any Emacs Lisp buffer and ask for the preceding sexp, you
get <code class="language-plaintext highlighter-rouge">hey</code>. CIDER now steps out of the comment first, which as far as I can
tell makes it the only one of the family that gets this right.<sup id="fnref:1" role="doc-noteref"><a href="#fn:1" class="footnote" rel="footnote">1</a></sup></p>

<h2 id="one-idea-worth-stealing">One idea worth stealing</h2>

<p>The same survey turned up something CIDER was missing. SLY briefly flashes the
region it compiled, so you <em>see</em> what it acted on. That’s a direct answer to
the confusion this whole saga was about - “which form did it just take?” -
and it changes nothing about what gets taken.</p>

<div class="language-emacs-lisp highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">(</span><span class="k">setq</span> <span class="nv">cider-flash-evaluated-region</span> <span class="no">t</span><span class="p">)</span>
</code></pre></div></div>

<p>Off by default, because I’ve learned my lesson about switching things on for
everyone. But if the targeting rules ever puzzle you, turn it on for a day.</p>

<h2 id="the-moral">The moral</h2>

<p>In the original post I described <code class="language-plaintext highlighter-rouge">cider-form-targeting</code>, the escape hatch back
to the classic rules, as “living on borrowed time” - clutter left over from a
plan I’d since reversed, which I was itching to delete.</p>

<p>That option is the only reason the conversation stayed a conversation. Its
existence made the objection “please don’t remove the fallback” rather than
“I’m forking CIDER”, and I very nearly removed it before anyone had tried the
change.</p>

<p>Every mistake is a learning experience for me, and this one was cheap: nothing
had shipped, so the whole thing cost a few days and some rewriting. The
testing and feedback cycle worked exactly as it should have - people tried
something on <code class="language-plaintext highlighter-rouge">master</code>, told me plainly what was wrong with it, and the result
is better than either what I proposed or what we had before. Everyone gets
the behaviour they want, and CIDER lost a text-eating bug on the way.</p>

<p>Thanks to everyone who took the time to tell me I was wrong.</p>

<p>That’s all I have for you today. Keep hacking!</p>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1" role="doc-endnote">
      <p>If you’re an Emacs maintainer reading this: <code class="language-plaintext highlighter-rouge">elisp--preceding-sexp</code> has the same behaviour, and I’d be happy to be told why it’s intentional. <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Bozhidar Batsov</name></author><category term="posts" /><category term="Emacs" /><category term="Clojure" /><category term="CIDER" /><summary type="html"><![CDATA[A couple of days ago I wrote that smarter form targeting was coming to CIDER, and I ended that post by asking whether I’d got the resolution rules right and whether anything still surprised people. I got an answer. CIDER 2.1 will ship with the classic behaviour intact.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://metaredux.com/assets/og-image.png" /><media:content medium="image" url="https://metaredux.com/assets/og-image.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Smarter Form Targeting Is Coming to CIDER</title><link href="https://metaredux.com/posts/2026/08/26/smarter-form-targeting-is-coming-to-cider.html" rel="alternate" type="text/html" title="Smarter Form Targeting Is Coming to CIDER" /><published>2026-08-26T09:18:00+00:00</published><updated>2026-08-26T09:18:00+00:00</updated><id>https://metaredux.com/posts/2026/08/26/smarter-form-targeting-is-coming-to-cider</id><content type="html" xml:base="https://metaredux.com/posts/2026/08/26/smarter-form-targeting-is-coming-to-cider.html"><![CDATA[<p>If I had a dollar for every time someone asked on the Clojurians Slack in
<code class="language-plaintext highlighter-rouge">#cider</code> why <code class="language-plaintext highlighter-rouge">C-x C-e</code> evaluated “the wrong thing”, I’d probably be writing this
post from a yacht.  The answer was always the same: the cursor wasn’t where
CIDER expected it to be. The <em>upcoming</em> CIDER 2.1 release changes that - the
evaluation commands now figure out which form you mean from where your cursor
actually is.</p>

<!--more-->

<p>NOTE: <strong>Update:</strong> this didn’t survive contact with its users, and CIDER 2.1
ships with the classic behaviour after all. See
/posts/2026/08/29/smarter-form-targeting-is-not-coming-to-cider.html for
what the feedback was, what replaced it, and the rather nasty bug the detour
turned up.</p>

<h2 id="a-bit-of-history">A bit of history</h2>

<p>Emacs has a very particular tradition when it comes to evaluating code:
<code class="language-plaintext highlighter-rouge">eval-last-sexp</code> (the venerable <code class="language-plaintext highlighter-rouge">C-x C-e</code>) acts on the expression <em>before</em> the
cursor. Not the one you’re looking at, not the one you’re inside of - the one
that ends exactly where your cursor stands. SLIME follows this tradition,
Emacs Lisp itself follows it, and for the past 15+ years CIDER has followed it
too.<sup id="fnref:1" role="doc-noteref"><a href="#fn:1" class="footnote" rel="footnote">1</a></sup> If you grew up in Emacs, this rule is in your fingers and you’ve
never once thought about it.</p>

<p>Here’s the thing, though - most people using CIDER didn’t grow up in Emacs.
And many of them never programmed in Emacs Lisp and Common Lisp with SLIME.
They came to Emacs <em>because of</em> CIDER (or Clojure in general), and for them
the rule is invisible, arbitrary and mildly hostile. You put your cursor on a
form, you press the eval key, and CIDER cheerfully evaluates… something
else. Meanwhile every other modern Clojure environment - Calva, Conjure, the
various vim plugins - resolves the form from the cursor position and just does
what you meant.<sup id="fnref:2" role="doc-noteref"><a href="#fn:2" class="footnote" rel="footnote">2</a></sup></p>

<p>For a long time I resisted changing this, mostly out of respect for the Emacs
tradition (and my own muscle memory). But at some point I had to admit that I
was optimizing for the wrong audience. CIDER’s users are mostly casual
Clojure hackers who happen to use Emacs, not Emacs experts who happen to
write Clojure. The tradition was serving me, and confusing them.</p>

<h2 id="whats-actually-changing">What’s actually changing</h2>

<p>The evaluation commands (and their macroexpansion, inspection and tapping
siblings) now resolve “the form the cursor indicates”. Concretely, with <code class="language-plaintext highlighter-rouge">|</code>
marking the cursor:</p>

<div class="language-clojure highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">(</span><span class="nb">map</span><span class="w"> </span><span class="nb">inc</span><span class="w"> </span><span class="err">|</span><span class="p">(</span><span class="nb">range</span><span class="w"> </span><span class="mi">10</span><span class="p">))</span><span class="w">
</span></code></pre></div></div>

<p>Pressing <code class="language-plaintext highlighter-rouge">C-c C-e</code> here used to evaluate <code class="language-plaintext highlighter-rouge">inc</code> - the form <em>before</em> the cursor,
which is almost never what you wanted. Now it evaluates <code class="language-plaintext highlighter-rouge">(range 10)</code> - the
form your cursor is pointing at.</p>

<div class="language-clojure highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">(</span><span class="nb">str</span><span class="w"> </span><span class="s">"hello"</span><span class="w"> </span><span class="s">" "</span><span class="w"> </span><span class="s">"world"</span><span class="err">|</span><span class="p">)</span><span class="w">
</span></code></pre></div></div>

<p>This one used to evaluate <code class="language-plaintext highlighter-rouge">"world"</code> (really!), because the last complete
expression before a cursor sitting on the closing paren is the final string.
Now it evaluates the whole <code class="language-plaintext highlighter-rouge">(str ...)</code> call.</p>

<p>Macroexpansion benefits too:</p>

<div class="language-clojure highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">(</span><span class="nb">when</span><span class="w"> </span><span class="n">tru</span><span class="err">|</span><span class="n">e</span><span class="w"> </span><span class="p">(</span><span class="nf">launch-missiles</span><span class="p">))</span><span class="w">
</span></code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">C-c C-m</code> here used to complain that <code class="language-plaintext highlighter-rouge">true</code> is not a macro. Now it expands the
enclosing <code class="language-plaintext highlighter-rouge">(when ...)</code> call, because expanding a bare symbol is never what
anyone means.</p>

<p>And my favorite one - the rich comment workflow is now consistent everywhere:</p>

<div class="language-clojure highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">(</span><span class="nb">comment</span><span class="w">
  </span><span class="p">(</span><span class="nf">calculate-all-the-things</span><span class="err">|</span><span class="p">))</span><span class="w">
</span></code></pre></div></div>

<p>Every defun-level command - eval, pretty-print, inspect, debug - now treats
the form inside the <code class="language-plaintext highlighter-rouge">(comment ...)</code> as the top-level one. Evaluating a whole
<code class="language-plaintext highlighter-rouge">comment</code> form returns <code class="language-plaintext highlighter-rouge">nil</code> by definition, which has exactly zero uses, so
CIDER no longer does that no matter which command you reach for.</p>

<h2 id="why-you-probably-wont-notice">Why you probably won’t notice</h2>

<p>Here’s the part I’m most pleased with: the new behavior agrees with the old
one at every position where “the form before the cursor” made sense. Cursor
right after a form? Same result as always. Cursor in the whitespace after a
form? Same. Cursor in the middle of a symbol? Same. The two behaviors only
diverge where the classic answer was something nobody ever wanted - a
previous sibling, a lone trailing atom.</p>

<p>So if your muscle memory follows the Emacs tradition, nothing changes for
you. If it doesn’t - CIDER stops punishing you for it. That’s the whole
change.</p>

<h2 id="reverting-to-the-classic-behavior-for-now">Reverting to the classic behavior (for now)</h2>

<p>If you <em>do</em> want the traditional rules - maybe you genuinely use
“evaluate the previous sibling while standing on an opening paren” - one
setting restores them exactly:</p>

<div class="language-emacs-lisp highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">(</span><span class="k">setq</span> <span class="nv">cider-form-targeting</span> <span class="ss">'preceding</span><span class="p">)</span>
</code></pre></div></div>

<p>There’s also a per-session toggle in the eval menu (<code class="language-plaintext highlighter-rouge">C-c C-v T</code>) that shows
the active mode in the mode line while you experiment.</p>

<p>This option is probably living on borrowed
time, though. I added it back when I planned to keep the classic behavior as the
default and offer smart targeting as an opt-in. Now that the roles are
reversed, an option whose only job is restoring rules almost nobody
deliberately relied on doesn’t really make much sense, and lately I’ve been
trying to trim that kind of clutter from CIDER, not add to it. Don’t be
surprised if the option quietly disappears - possibly even before the release
ships. Which is one more reason to speak up now if the classic behavior
genuinely matters to you.</p>

<h2 id="farewell-last-sexp">Farewell, “last sexp”</h2>

<p>This change forced my hand on something I’d been putting off for years - the
command names. <code class="language-plaintext highlighter-rouge">cider-eval-last-sexp</code> is a fine name for a command that
evaluates the last sexp. It’s a lie for a command that evaluates the form
your cursor indicates. So the commands got honest names:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">cider-eval-last-sexp</code> is now <code class="language-plaintext highlighter-rouge">cider-eval-form</code></li>
  <li><code class="language-plaintext highlighter-rouge">cider-eval-defun-at-point</code> is now <code class="language-plaintext highlighter-rouge">cider-eval-defun</code> (the <code class="language-plaintext highlighter-rouge">-at-point</code>
never carried information)</li>
  <li>likewise for the pprint/tap/inspect/insert variants</li>
</ul>

<p>Every old name keeps working as an alias, so your config and your <code class="language-plaintext highlighter-rouge">M-x</code>
habits are safe. But why “form” and not “sexp”? Beyond the targeting change,
there’s a Clojure-specific reason: in Clojure a <em>form</em> isn’t always a single
sexp. <code class="language-plaintext highlighter-rouge">^:private x</code> is two sexps but one form; so is <code class="language-plaintext highlighter-rouge">#inst "2024-01-01"</code>.
The commands operate on forms - the reader’s unit of evaluation - and now
they say so.<sup id="fnref:3" role="doc-noteref"><a href="#fn:3" class="footnote" rel="footnote">3</a></sup> The manual’s evaluation docs got a proper glossary
explaining all of this.</p>

<h2 id="closing-thoughts">Closing thoughts</h2>

<p>All of this is on <code class="language-plaintext highlighter-rouge">master</code> and in the MELPA snapshots today, ahead of the
next stable release. I’d really love for people to play with it <em>before</em> the
release ships - especially if you’re an Emacs veteran whose fingers disagree
with my reasoning, or a newcomer for whom this was supposed to just work. Did
we get the resolution rules right? Does anything still surprise you?</p>

<p>Share your feedback on the <a href="https://github.com/clojure-emacs/cider/discussions">CIDER discussions</a> board, in
<code class="language-plaintext highlighter-rouge">#cider</code> on the Clojurians Slack, or just file an issue. This is exactly the
kind of change that’s easy to adjust before a release and painful after -
and the fate of the compatibility option depends on what I hear.</p>

<p>That’s all I have for you today. Keep hacking!</p>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1" role="doc-endnote">
      <p>CIDER started its life as a SLIME “clone” for Clojure, after all - the tradition runs deep. <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:2" role="doc-endnote">
      <p>Interestingly, Cursive is the only major non-Emacs Clojure environment that kept the classic “form before the caret” model. <a href="#fnref:2" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:3" role="doc-endnote">
      <p>This also explains a subtlety Emacs veterans might appreciate: plain <code class="language-plaintext highlighter-rouge">forward-sexp</code> movement doesn’t know that Clojure metadata belongs to the form it annotates, which is why clojure-mode has always needed its own “logical sexp” movement functions. The new targeting is built on those, so metadata is never silently dropped from what you evaluate. <a href="#fnref:3" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Bozhidar Batsov</name></author><category term="posts" /><category term="Emacs" /><category term="Clojure" /><category term="CIDER" /><summary type="html"><![CDATA[If I had a dollar for every time someone asked on the Clojurians Slack in #cider why C-x C-e evaluated “the wrong thing”, I’d probably be writing this post from a yacht. The answer was always the same: the cursor wasn’t where CIDER expected it to be. The upcoming CIDER 2.1 release changes that - the evaluation commands now figure out which form you mean from where your cursor actually is.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://metaredux.com/assets/og-image.png" /><media:content medium="image" url="https://metaredux.com/assets/og-image.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Projectile 3.4</title><link href="https://metaredux.com/posts/2026/08/13/projectile-3-4.html" rel="alternate" type="text/html" title="Projectile 3.4" /><published>2026-08-13T07:30:00+00:00</published><updated>2026-08-13T07:30:00+00:00</updated><id>https://metaredux.com/posts/2026/08/13/projectile-3-4</id><content type="html" xml:base="https://metaredux.com/posts/2026/08/13/projectile-3-4.html"><![CDATA[<p><a href="https://github.com/bbatsov/projectile/releases/tag/v3.4.0">Projectile 3.4</a> is out! After
the four releases that preceded it this summer, this one is polish rather than ambition.</p>

<p>Most of it came out of an annoyance I’d been living with for years without ever quite
naming it: a lot of what I work on isn’t one directory. <a href="https://github.com/clojure-emacs/cider">CIDER</a> is really CIDER plus
<a href="https://github.com/clojure-emacs/cider-nrepl">cider-nrepl</a> plus <a href="https://github.com/clojure-emacs/orchard">orchard</a> plus <a href="https://github.com/clojure-emacs/clj-refactor.el">clj-refactor</a> plus a
handful of others. <a href="https://github.com/rubocop/rubocop">RuboCop</a> is RuboCop plus <a href="https://github.com/rubocop/rubocop-ast">rubocop-ast</a> plus
<a href="https://github.com/rubocop/rubocop-rails">rubocop-rails</a> and the other extension gems plus <a href="https://github.com/rubocop/ruby-style-guide">the style
guide</a>. I’ve been maintaining families of repositories for the better
part of a decade.</p>

<p>Lately I’ve also been reaching for git worktrees far more than I used to, so the same
repository is now checked out two or three times on my disk at any given moment.</p>

<p>Projectile saw all of that as a pile of unrelated projects, which is exactly what it looks
like from the outside.</p>

<!--more-->

<h2 id="somewhere-else-in-the-same-project">Somewhere else in the same project</h2>

<p><code class="language-plaintext highlighter-rouge">projectile-switch-worktree</code> (<code class="language-plaintext highlighter-rouge">s-p W</code>) offers the other checkouts of the repository you’re
in, each labelled with whatever tells it apart - the branch for git, the workspace name for
Jujutsu:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Switch to worktree:
~/src/myapp-main/     (main)
~/src/myapp-hotfix/   (hotfix/crash-on-open)
</code></pre></div></div>

<p>Git worktrees are the obvious case. Projectile asks git about those, so a worktree you’ve
never opened in Emacs shows up anyway. Jujutsu workspaces work the same way.</p>

<p>The case I care about more is the one without any plumbing: a second <code class="language-plaintext highlighter-rouge">git clone</code> of the
same upstream. Same workflow, done by hand. I looked at my own <code class="language-plaintext highlighter-rouge">~/projects</code> while writing
this and found four separate clones of CIDER sitting in it. Nothing records those anywhere,
so Projectile can’t ask git to list them - it matches them among your known projects by
their remote instead.</p>

<h2 id="somewhere-else-in-the-same-effort">Somewhere else in the same <em>effort</em></h2>

<p>The other half is <code class="language-plaintext highlighter-rouge">projectile-switch-sibling-project</code> (<code class="language-plaintext highlighter-rouge">s-p n</code>), which offers the projects
related to the one you’re in rather than every project on the machine.</p>

<p>The interesting question was what “related” should mean. My first instinct was to compare
directory names and look for a shared prefix. Before writing anything I tried the
candidates out on my actual project directory, all ninety-odd repositories of it.</p>

<p>Comparing names does find <code class="language-plaintext highlighter-rouge">rubocop</code>, <code class="language-plaintext highlighter-rouge">rubocop-ast</code> and <code class="language-plaintext highlighter-rouge">rubocop-rails</code>. But grouping by the
<em>owner of the upstream remote</em> finds this:</p>

<p><img src="/assets/images/projectile-sibling-projects.png" alt="The sibling project prompt in CIDER, listing sixteen related projects including orchard, haystack, port and sayid" /></p>

<p>Half of those names have nothing in common with <code class="language-plaintext highlighter-rouge">cider</code>, and no amount of staring at
directory names would ever have related them. <a href="https://github.com/clojure-emacs/haystack">haystack</a> parses stack traces,
<a href="https://github.com/clojure-emacs/port">port</a> is a printer registry, <a href="https://github.com/clojure-emacs/sayid">sayid</a> is a tracing debugger. Nothing in those
names says “CIDER”.</p>

<p>What they do have in common is an org: they all live under
<a href="https://github.com/clojure-emacs">clojure-emacs</a> on GitHub. That’s not incidental, it’s how the project is
actually organised - the org is the boundary of the effort, and the individual repositories
are just where the pieces ended up when they got big enough to split out. Same story for
the <a href="https://github.com/rubocop">rubocop</a> org, and for <a href="https://github.com/nrepl">nrepl</a>. Once I saw that, keying on the
owner of the remote was obviously right, because it’s the same fact GitHub is already
recording for me.</p>

<p>It needs a bound, though, and the same experiment showed why: about 40% of my checkouts are
under my own GitHub account, and “we’re both under <code class="language-plaintext highlighter-rouge">bbatsov</code>” doesn’t relate anything. So an
inferred group covering more than a quarter of your known projects gets dropped and the
next signal takes over.<sup id="fnref:1" role="doc-noteref"><a href="#fn:1" class="footnote" rel="footnote">1</a></sup> If you’d rather just say what belongs together,
<code class="language-plaintext highlighter-rouge">projectile-project-groups</code> is there and is never second-guessed.</p>

<p>Switching is only the obvious thing to do with this. Now that Projectile can tell which
projects belong together, the same grouping could back a find-file or a search across the
whole family - one prompt that reaches every repository in the org rather than just the one
you happen to be sitting in. I go looking for “which of these fifteen repos defines this
var” often enough that I suspect it’s the more useful half. Nothing built yet, but that’s
where I expect this to go.</p>

<h2 id="the-commands-come-with-you">The commands come with you</h2>

<p>Once Projectile knows two directories are the same repository, the command history can
follow you between them.</p>

<p>Press <code class="language-plaintext highlighter-rouge">M-p</code> at the compile or test prompt in a worktree you made this morning and you get
the commands the project is actually built with, instead of an empty history. That’s <a href="https://github.com/bbatsov/projectile/issues/1786">an
issue from 2022</a> that a stale bot had
helpfully closed for me at some point.</p>

<p>What doesn’t follow you is anything that runs without asking - what a prompt is pre-filled
with, and what <code class="language-plaintext highlighter-rouge">projectile-repeat-last-command</code> replays. I had those shared too in the
first draft, and then watched a repeat in one worktree rebuild the tree next door. A
remembered command can carry absolute paths back to where it was typed.</p>

<h2 id="more-languages-fewer-surprises">More languages, fewer surprises</h2>

<p><code class="language-plaintext highlighter-rouge">projectile-run-test-at-point</code> (<code class="language-plaintext highlighter-rouge">s-p c .</code>) arrived in 3.1 knowing Python, Go and JS/TS. It
now also knows Ruby (both RSpec and Minitest), Rust, Elixir, Java, Erlang and F#.</p>

<p>Ruby is written the same way whichever framework you use, so there the project type picks
the runner rather than the syntax; Java’s picks between Maven and Gradle. Elixir tests get
addressed as <code class="language-plaintext highlighter-rouge">FILE:LINE</code>, because ExUnit can’t select a test by name from the command line.
OCaml deliberately gets nothing - its tests are ordinary values you register with Alcotest
or OUnit, so there’s no syntax to recognize.</p>

<p><code class="language-plaintext highlighter-rouge">projectile-find-file-of-kind</code> (<code class="language-plaintext highlighter-rouge">s-p j</code>) and <code class="language-plaintext highlighter-rouge">projectile-toggle-related-file</code> (<code class="language-plaintext highlighter-rouge">s-p J</code>)
learned Phoenix, Laravel and Next.js. Rails and Django had been the only frameworks with
file-kinds tables out of the box, which felt like a strange place to have stopped.</p>

<h2 id="the-reports-answer-back">The reports answer back</h2>

<p>The dashboard and the doctor from 3.3 both got a pass. They’re no longer plain text -
section headers, field labels and findings are faced by meaning, with findings colored by
severity and sorted so anything wanting your attention comes first. The faces only inherit
from standard ones, so your theme styles them without knowing Projectile exists.</p>

<p>The doctor’s findings now come with a button that acts on them:</p>

<p><img src="/assets/images/projectile-doctor-findings.png" alt="The doctor's findings section, with a warning about projectile-mode carrying an enable button, above four ok findings" /></p>

<p><code class="language-plaintext highlighter-rouge">[enable]</code> for a <code class="language-plaintext highlighter-rouge">projectile-mode</code> you forgot to turn on, <code class="language-plaintext highlighter-rouge">[enable caching]</code> on a big
uncached project, <code class="language-plaintext highlighter-rouge">[open dirconfig]</code>, <code class="language-plaintext highlighter-rouge">[edit .dir-locals.el]</code>. Pressing one regenerates the
report. Findings Projectile can’t act on stay plain advice.</p>

<p>And since a doctor report usually ends up pasted into an issue, <code class="language-plaintext highlighter-rouge">w</code> copies the buffer as
plain text, without the faces and buttons.</p>

<h2 id="odds-and-ends">Odds and ends</h2>

<ul>
  <li><code class="language-plaintext highlighter-rouge">projectile-find-changed-file</code> (<code class="language-plaintext highlighter-rouge">s-p C</code>) completes over what git reports as staged,
unstaged or untracked - or, with a prefix argument, everything that differs from a
revision you pick.</li>
  <li><code class="language-plaintext highlighter-rouge">projectile-run-task</code> discovers rake tasks now, read out of your <code class="language-plaintext highlighter-rouge">Rakefile</code> and <code class="language-plaintext highlighter-rouge">.rake</code>
files rather than by running <code class="language-plaintext highlighter-rouge">rake -T</code>, which would load the whole application.</li>
  <li><code class="language-plaintext highlighter-rouge">projectile-ignored-project-patterns</code> is the regexp-matching sibling of
<code class="language-plaintext highlighter-rouge">projectile-ignored-projects</code>, so keeping a whole area of your machine out of the known
projects no longer needs a lambda.</li>
  <li>Messages Projectile emits on its own initiative are prefixed with <code class="language-plaintext highlighter-rouge">[Projectile]</code> now, and
the ones answering a command you just invoked aren’t. There were five different
conventions in there before, which I’d somehow never noticed.</li>
  <li>The known projects file, the frecency store and the session directory are resolved with
<code class="language-plaintext highlighter-rouge">locate-user-emacs-file</code>, so they land in the right place if your configuration lives in
<code class="language-plaintext highlighter-rouge">~/.config/emacs</code>. Nothing moves if it doesn’t.</li>
  <li>Elixir’s implementation/test toggle offers <code class="language-plaintext highlighter-rouge">foo_test.exs</code> rather than <code class="language-plaintext highlighter-rouge">foo_test.ex</code>, a
script ExUnit will actually run. Project types can declare their test file extension now.</li>
</ul>

<h2 id="upgrade-notes">Upgrade notes</h2>

<p>Nothing here should break a working setup, but two things are worth knowing.</p>

<p>A batch of options were renamed or folded together. The six
<code class="language-plaintext highlighter-rouge">projectile-&lt;cmd&gt;-use-comint-mode</code> options became one <code class="language-plaintext highlighter-rouge">projectile-use-comint-mode</code>;
<code class="language-plaintext highlighter-rouge">projectile-per-project-compilation-buffer</code> and <code class="language-plaintext highlighter-rouge">projectile-per-command-compilation-buffer</code>
became <code class="language-plaintext highlighter-rouge">projectile-compilation-buffer-scope</code>; and a handful of options that had broken
their own naming schemes were renamed to match their siblings.<sup id="fnref:2" role="doc-noteref"><a href="#fn:2" class="footnote" rel="footnote">2</a></sup> <strong>Every one of them is
still honored under its old name</strong>, so your config keeps working - you’ll just see an
obsolescence notice.</p>

<p>Two options are gone: <code class="language-plaintext highlighter-rouge">projectile-tags-file-name</code> and <code class="language-plaintext highlighter-rouge">projectile-go-project-test-function</code>
were only ever read as Projectile loaded, which means setting them from your init file
afterwards did precisely nothing.</p>

<p>And the command history is now the repository’s rather than the directory’s. Set
<code class="language-plaintext highlighter-rouge">projectile-command-history-scope</code> to <code class="language-plaintext highlighter-rouge">project</code> if you’d rather have it per directory.
Histories you already have are adopted, not dropped.</p>

<p>The full changelog is
<a href="https://github.com/bbatsov/projectile/blob/master/CHANGELOG.md">here</a>, and the manual is
at <a href="https://docs.projectile.mx/">docs.projectile.mx</a>. The cross-repository features have a
<a href="https://docs.projectile.mx/projectile/3.4/across_repositories.html">page of their own</a>,
limitations included.</p>

<p>Five releases in six weeks is not a pace I intend to keep up, and this is the natural place
for the burst to land. The big pieces from 3.0 through 3.3 have had their corners sanded
down, and what’s left on my list is smaller and less interesting to write about. Which is
roughly where a fifteen-year-old package ought to be.</p>

<p>That’s all I have for you today. Keep hacking!</p>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1" role="doc-endnote">
      <p>Which is why <code class="language-plaintext highlighter-rouge">projectile</code> itself comes back with no siblings on my machine. The cap is working; the answer is a configured group. <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:2" role="doc-endnote">
      <p><code class="language-plaintext highlighter-rouge">projectile-global-ignore-file-patterns</code>, <code class="language-plaintext highlighter-rouge">projectile-cmd-hist-ignoredups</code>, <code class="language-plaintext highlighter-rouge">projectile-related-files-fn-function</code>, <code class="language-plaintext highlighter-rouge">projectile-auto-discover</code>, and the three reviewable-search options that were named after replace. <a href="#fnref:2" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Bozhidar Batsov</name></author><category term="posts" /><category term="Emacs" /><category term="Projectile" /><summary type="html"><![CDATA[Projectile 3.4 is out! After the four releases that preceded it this summer, this one is polish rather than ambition. Most of it came out of an annoyance I’d been living with for years without ever quite naming it: a lot of what I work on isn’t one directory. CIDER is really CIDER plus cider-nrepl plus orchard plus clj-refactor plus a handful of others. RuboCop is RuboCop plus rubocop-ast plus rubocop-rails and the other extension gems plus the style guide. I’ve been maintaining families of repositories for the better part of a decade. Lately I’ve also been reaching for git worktrees far more than I used to, so the same repository is now checked out two or three times on my disk at any given moment. Projectile saw all of that as a pile of unrelated projects, which is exactly what it looks like from the outside.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://metaredux.com/assets/og-image.png" /><media:content medium="image" url="https://metaredux.com/assets/og-image.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">RuboCop 1.89: Project-Wide Analysis with Rubydex</title><link href="https://metaredux.com/posts/2026/08/05/rubocop-1-89.html" rel="alternate" type="text/html" title="RuboCop 1.89: Project-Wide Analysis with Rubydex" /><published>2026-08-05T07:00:00+00:00</published><updated>2026-08-05T07:00:00+00:00</updated><id>https://metaredux.com/posts/2026/08/05/rubocop-1-89</id><content type="html" xml:base="https://metaredux.com/posts/2026/08/05/rubocop-1-89.html"><![CDATA[<p><a href="https://github.com/rubocop/rubocop/releases/tag/v1.89.0">RuboCop 1.89</a> is out, and it comes with the usual assortment of new cops
and bug fixes. But there’s one theme running through this release that I’m
particularly excited about, and that’s what I want to talk about today: RuboCop
is finally learning to look beyond a single file.</p>

<!--more-->

<h2 id="the-single-file-curse-limitation">The single-file curse (limitation)</h2>

<p>For its entire existence RuboCop has analyzed your code one file at a time. That’s
not an accident - it’s a deliberate design choice that has served the project
extremely well. A file-at-a-time analyzer is simple, it’s fast, and it
parallelizes trivially across all your cores. It’s a big part of why RuboCop can
lint a huge codebase in a few seconds.</p>

<p>The catch is that a cop looking at a single file is essentially working with
blinders on. It has no idea what’s defined in the rest of your project. And that
turns out to be a real limitation for a whole class of checks:</p>

<ul>
  <li>Is this method a duplicate of one defined in another file? No way to tell.</li>
  <li>Does this constant actually refer to what I think it does, given the surrounding
namespaces? Can’t resolve it without the whole picture.</li>
  <li>Does this class really need a <code class="language-plaintext highlighter-rouge">super</code> call in its constructor, or does none of
its ancestors define <code class="language-plaintext highlighter-rouge">initialize</code>? RuboCop can’t see the ancestry, so it has to
play it safe.</li>
</ul>

<p>Faced with questions like these, cops have only ever had two options: bail out and
say nothing (a false negative), or guess and risk yelling at perfectly good code
(a false positive). Neither is great. Over the years we’ve papered over this with
configuration knobs - things like <code class="language-plaintext highlighter-rouge">AllowedParentClasses</code> for <code class="language-plaintext highlighter-rouge">Lint/MissingSuper</code>,
where you manually list the base classes RuboCop can’t see for itself. It works,
but it’s the kind of busywork a tool should be doing for you.</p>

<h2 id="enter-rubydex">Enter rubydex</h2>

<p><a href="https://github.com/Shopify/rubydex">rubydex</a> is a library from Shopify that does exactly what RuboCop
historically couldn’t: it builds a project-wide index of your code - a graph of
every declaration and reference, with the ancestry and resolution worked out. Give
a cop access to that index and suddenly it can answer all those cross-file
questions with confidence.</p>

<p>We introduced optional support for rubydex back in <a href="https://docs.rubocop.org/rubocop/usage/project_index.html">1.87</a>, and 1.89
is where it really starts to pay off.</p>

<p>I want to stress the word <em>optional</em> here. rubydex is a separate gem with native
(Rust) extensions, and using it means paying for an indexing pass and some extra
memory. That’s a perfectly reasonable trade for the extra smarts, but it’s not a
trade everyone wants to make, and it shouldn’t be forced on anyone. RuboCop’s
default experience should stay lean and dependency-light - no native code, no
index, no surprises. So rubydex is opt-in, and I fully expect it’ll stay that way
for the foreseeable future. If you want the cross-file superpowers, you flip a
switch; if you don’t, nothing changes for you.</p>

<p>Turning it on is two steps. Add the gem to your <code class="language-plaintext highlighter-rouge">Gemfile</code>:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">gem</span> <span class="s1">'rubydex'</span><span class="p">,</span> <span class="ss">require: </span><span class="kp">false</span>
</code></pre></div></div>

<p>And enable the flag in your <code class="language-plaintext highlighter-rouge">.rubocop.yml</code>:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">AllCops</span><span class="pi">:</span>
  <span class="na">UseProjectIndex</span><span class="pi">:</span> <span class="no">true</span>
</code></pre></div></div>

<p>Everything below happens automatically once the index is available - there’s no
per-cop opt-in. And if the gem isn’t installed, RuboCop just prints a friendly
warning and falls back to its usual file-local behavior.</p>

<h2 id="what-the-index-unlocks-in-189">What the index unlocks in 1.89</h2>

<p>This release wires the index into a good chunk of the cop library. Here’s a tour
of what you get.</p>

<p>There are a few brand-new cops that simply couldn’t exist without a project-wide
view:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">Lint/NameTypo</code> is my personal favorite - it catches typos in constant and
method names by checking them against everything defined in your project and
suggesting the closest match. So <code class="language-plaintext highlighter-rouge">Services::UserCraetor.new</code> gets flagged with a
helpful “did you mean <code class="language-plaintext highlighter-rouge">UserCreator</code>?”, and the same goes for a fat-fingered
method call like <code class="language-plaintext highlighter-rouge">Report.generate_sumary</code>. It’s careful to only speak up when
it’s confident (the name has to be unresolvable <em>and</em> have a close sibling), so
it stays quiet on genuinely external names.</li>
  <li><code class="language-plaintext highlighter-rouge">Lint/DeprecatedReference</code> flags calls and constant references to any API you’ve
marked with a YARD <code class="language-plaintext highlighter-rouge">@deprecated</code> tag, anywhere in the project. Tag a method as
deprecated in one file, and every stray use of it elsewhere lights up. It’s a
lovely way to drive a gradual migration off some old code.</li>
  <li><code class="language-plaintext highlighter-rouge">Lint/UnusedPrivateMethod</code> does project-wide dead-code detection - it reports
private methods that are never referenced anywhere in the indexed project. It’s
disabled by default and best used as an occasional sweep, since it can’t see
reflective calls, but it’s great for a spring cleaning.</li>
</ul>

<p>A whole bunch of existing cops got sharper too, either catching things they used
to miss or backing off where they used to nag:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">Lint/DuplicateMethods</code> now catches duplicates that live in <em>different</em> files -
the same method defined twice across two files was previously invisible to it.
If you’re deliberately redefining a method (a monkey patch, say), the self-alias
trick (<code class="language-plaintext highlighter-rouge">alias foo foo</code> right before the redefinition) signals your intent and
keeps things quiet.</li>
  <li><code class="language-plaintext highlighter-rouge">Lint/ConstantReassignment</code> likewise catches a constant that’s reassigned in
another file, not just within the current one.</li>
  <li><code class="language-plaintext highlighter-rouge">Lint/MissingSuper</code> no longer nags you about a missing <code class="language-plaintext highlighter-rouge">super</code> when the index can
prove that none of the class’s ancestors actually defines <code class="language-plaintext highlighter-rouge">initialize</code> - in that
case <code class="language-plaintext highlighter-rouge">super</code> would only reach the no-op <code class="language-plaintext highlighter-rouge">Object#initialize</code>. This is the one that
makes those <code class="language-plaintext highlighter-rouge">AllowedParentClasses</code> lists mostly unnecessary; RuboCop figures out
your abstract base classes on its own now.</li>
  <li><code class="language-plaintext highlighter-rouge">Lint/ConstantResolution</code> used to be so noisy it was practically unusable without
a pile of <code class="language-plaintext highlighter-rouge">Only</code>/<code class="language-plaintext highlighter-rouge">Ignore</code> configuration. With the index it reports only genuinely
ambiguous constants - ones that resolve differently through the surrounding
nesting than they would fully qualified - which finally makes it practical to
turn on.</li>
  <li><code class="language-plaintext highlighter-rouge">Lint/InheritException</code> now spots classes that inherit from <code class="language-plaintext highlighter-rouge">Exception</code>
indirectly, through a parent class defined elsewhere in your project.</li>
  <li><code class="language-plaintext highlighter-rouge">Style/Documentation</code> accepts a reopened class or module as documented as long as
<em>any</em> of its definition sites carries a doc comment, so you’re not forced to
repeat yourself at every reopening.</li>
  <li>A cluster of cops learned to stop producing false positives once they can see the
whole picture: <code class="language-plaintext highlighter-rouge">Style/MissingRespondToMissing</code> accepts a <code class="language-plaintext highlighter-rouge">respond_to_missing?</code>
defined in another reopening of the class; <code class="language-plaintext highlighter-rouge">Style/StaticClass</code> leaves alone
classes that are subclassed elsewhere; <code class="language-plaintext highlighter-rouge">Style/RedundantConstantBase</code> can now flag
a redundant leading <code class="language-plaintext highlighter-rouge">::</code> inside a namespace when it proves the constant resolves
identically without it; and <code class="language-plaintext highlighter-rouge">Naming/PredicatePrefix</code> and
<code class="language-plaintext highlighter-rouge">Naming/AccessorMethodName</code> stop suggesting renames for methods that override an
ancestor defined elsewhere in the project.</li>
  <li><code class="language-plaintext highlighter-rouge">Style/ClassAndModuleChildren</code> uses the index to make its (unsafe) autocorrection
a lot more reliable - it resolves the real namespace kind (<code class="language-plaintext highlighter-rouge">class</code> vs <code class="language-plaintext highlighter-rouge">module</code>)
instead of guessing, and skips compacting a definition when doing so would blow
up with a <code class="language-plaintext highlighter-rouge">NameError</code> at load time.</li>
</ul>

<p>And a couple of things happening under the hood are worth calling out:</p>

<ul>
  <li>The index now always covers your whole project, regardless of which files a
particular run happens to inspect. That means linting a single file reports the
same cross-file offenses as a full run - no more results that depend on how you
invoked RuboCop.</li>
  <li>If you want ancestry chains that reach into your gems to resolve too (think a
model inheriting from a framework base class), the new
<code class="language-plaintext highlighter-rouge">AllCops/ProjectIndexIncludesGems</code> option indexes your bundle’s sources as well.
On RuboCop’s own repo that took the share of classes with a fully resolvable
ancestry from about 20% to about 97%, at the cost of some extra memory.</li>
  <li>The language server got smarter about the index - it now builds it once per
session and reuses it across requests, rebuilding only when you save a file, so
editing a buffer doesn’t pay the indexing cost on every keystroke.</li>
</ul>

<h2 id="still-early-days">Still early days</h2>

<p>I don’t want to oversell any of this. We’re at the very beginning of RuboCop’s
cross-file journey, and there’s a lot we haven’t tackled yet. The list of checks
that would benefit from a project-wide view is long, and I suspect the most
interesting applications are still ahead of us. rubydex itself is young and
evolving, and so is our integration with it.</p>

<p>But I think it’s a genuinely promising start. A year ago the idea of RuboCop
catching a constant typo across files, or reasoning about a class’s real ancestry,
would have been a non-starter. Now it’s a config flag away.</p>

<p>If any of this sounds useful, I’d love for you to give it a try - add <code class="language-plaintext highlighter-rouge">rubydex</code> to
your <code class="language-plaintext highlighter-rouge">Gemfile</code>, flip <code class="language-plaintext highlighter-rouge">UseProjectIndex</code> on, and see what it turns up in your
codebase. And please <a href="https://github.com/rubocop/rubocop/issues">tell us how it goes</a>. The feature is still marked
experimental, and real-world feedback is exactly what we need to figure out where
to take it next. Bug reports, false positives, ideas for new cross-file cops - all
of it is welcome.</p>

<p>Big thanks to everyone who has been kicking the tires on the project index and
reporting their findings. Here’s to seeing beyond a single file.</p>

<p>Keep hacking!</p>]]></content><author><name>Bozhidar Batsov</name></author><category term="posts" /><category term="Ruby" /><category term="RuboCop" /><summary type="html"><![CDATA[RuboCop 1.89 is out, and it comes with the usual assortment of new cops and bug fixes. But there’s one theme running through this release that I’m particularly excited about, and that’s what I want to talk about today: RuboCop is finally learning to look beyond a single file.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://metaredux.com/assets/og-image.png" /><media:content medium="image" url="https://metaredux.com/assets/og-image.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Leveling Up CIDER’s ClojureScript Support</title><link href="https://metaredux.com/posts/2026/07/29/leveling-up-ciders-clojurescript-support.html" rel="alternate" type="text/html" title="Leveling Up CIDER’s ClojureScript Support" /><published>2026-07-29T14:00:00+00:00</published><updated>2026-07-29T14:00:00+00:00</updated><id>https://metaredux.com/posts/2026/07/29/leveling-up-ciders-clojurescript-support</id><content type="html" xml:base="https://metaredux.com/posts/2026/07/29/leveling-up-ciders-clojurescript-support.html"><![CDATA[<p>Continuing the series on the notable changes in
<a href="/posts/2026/07/15/cider-2-0.html">CIDER 2.0</a>, let’s talk about
ClojureScript - forever the trickier sibling in the CIDER family.</p>

<p>I’ll start with a confession I’ve made before: I rarely use ClojureScript
myself, which is a big part of why its support in CIDER has historically lagged
behind Clojure’s. Every “State of CIDER” survey reminds me of this, usually in
the comments section, occasionally in all caps. So in the 2.0 cycle I decided
to stop feeling vaguely guilty about it and actually do something - across
every layer of the stack: CIDER itself, <code class="language-plaintext highlighter-rouge">cider-nrepl</code>, and
<a href="https://github.com/nrepl/piggieback">Piggieback</a>.</p>

<h2 id="first-a-strategic-decision">First, a strategic decision</h2>

<p>The most important ClojureScript change in CIDER 2.0 isn’t a feature - it’s a
decision about what <em>not</em> to build. Some of CIDER’s most powerful tools (the
debugger, enlighten, tracing, profiling) are deeply tied to JVM runtime
introspection, and porting them to ClojureScript would be a massive effort with
a poor cost/benefit ratio. Rather than keeping them in eternal “maybe someday”
limbo, we’ve explicitly scoped them as Clojure-only and focused the actual work
on the things cljs users hit every day: evaluation, testing, error reporting,
and clear behavior everywhere else.</p>

<p>That last part matters more than it sounds. Historically, invoking a
JVM-only command in a ClojureScript REPL would fail in some confusing way - a
cryptic error, a JVM-flavored result, or silence. Now the ops themselves report
a <code class="language-plaintext highlighter-rouge">clojure-only</code> status, and CIDER tells you plainly that the command isn’t
supported for ClojureScript. Knowing what a tool <em>won’t</em> do is half of trusting
it.</p>

<h2 id="what-actually-got-better">What actually got better</h2>

<ul>
  <li>The regular test commands (<code class="language-plaintext highlighter-rouge">cider-test-run-ns-tests</code> and
friends) now work in ClojureScript REPLs, asynchronous <code class="language-plaintext highlighter-rouge">cljs.test/async</code>
tests included. Previously CIDER just refused, and you were stuck evaluating
<code class="language-plaintext highlighter-rouge">(run-tests)</code> by hand like an animal.</li>
  <li>Expanding your own macros (e.g.
ones brought in via <code class="language-plaintext highlighter-rouge">:refer-macros</code>) used to silently echo the form back
unexpanded - a bug filed all the way back in
<a href="https://github.com/clojure-emacs/cider/issues/2099">2017</a>. The compiler
environment is now threaded to the analyzer properly, and it just works.</li>
  <li><code class="language-plaintext highlighter-rouge">cider-nrepl</code> now resolves the
ClojureScript compiler environment through a provider chain, with a dedicated
shadow-cljs provider - so the static-analysis ops keep working in a shadow
REPL that never loads Piggieback.</li>
  <li>The new <code class="language-plaintext highlighter-rouge">cider-tap</code> viewer works with ClojureScript
too: a runtime helper buffers tapped values and the JVM side streams them to
Emacs. (Tapped cljs values aren’t inspectable - they live in the JS runtime -
but you see them as they happen.)</li>
  <li>ClojureScript stack frames now render their
<code class="language-plaintext highlighter-rouge">ns/fn</code> properly instead of degrading to <code class="language-plaintext highlighter-rouge">nil/nil</code>, and unqualified core vars
resolve against <code class="language-plaintext highlighter-rouge">cljs.core</code> rather than falling back to <code class="language-plaintext highlighter-rouge">clojure.core</code>
(which quietly broke things like indentation metadata).</li>
  <li>A recent ClojureScript on the classpath (whose
Closure compiler wants JDK 21+) no longer crashes <code class="language-plaintext highlighter-rouge">cider-nrepl</code> at startup on
an older JDK - you get a Clojure-only session instead of no session.</li>
  <li>Piggieback itself got a round of bug fixes in the
0.6.x/0.7.0 releases - it’s easy to forget it exists (which is rather the
point of it), but it powers most cljs REPLs CIDER talks to.</li>
</ul>

<p>The documentation kept pace too: the new
<a href="https://docs.cider.mx/cider/cljs/up_and_running.html#full-stack-clojure-clojurescript-projects">full-stack Clojure + ClojureScript guide</a>
covers the two-REPLs-one-project setup that trips up nearly everyone, and the
<a href="https://docs.cider.mx/cider/cljs/overview.html">ClojureScript docs</a> got a
general refresh.</p>

<h2 id="an-unexpected-assist">An unexpected assist</h2>

<p>Fun aside: this is the area where AI coding agents helped me the most during
the 2.0 cycle. My ClojureScript experience is limited, but between the
excellent bug reports from the community and the ability to quickly prototype
and test fixes against real shadow-cljs and figwheel setups, problems that had
been “someone who knows cljs should look at this someday” for years finally got
fixed. Make of that what you will.</p>

<h2 id="whats-next">What’s next</h2>

<p>I keep pondering some form of “native” shadow-cljs support, given that
shadow-cljs is what most ClojureScript users actually run these days. That’s
still very much in the hammock phase, so don’t hold me to it - but the
direction is clear: fewer moving parts, clearer errors, and honesty about
what’s supported.</p>

<p>If you’re a ClojureScript user, I’d genuinely love to hear how 2.0 feels in
your daily work - the feedback loop is what keeps this improving. Keep hacking!</p>

<h2>Articles in the Series</h2>

<ul>

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

  
    <li><a href="/posts/2026/07/15/cider-2-0.html">CIDER 2.0: Sky is the Limit</a></li>
    <!-- tags if -->

  
    <li><a href="/posts/2026/07/16/simplifying-session-management-in-cider.html">Simplifying Session Management in CIDER</a></li>
    <!-- tags if -->

    <!-- tags if -->

  
    <li><a href="/posts/2026/07/17/stepping-through-macros-in-cider.html">Stepping Through Macros in CIDER</a></li>
    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

  
    <li><a href="/posts/2026/07/23/making-cider-more-discoverable.html">Making CIDER More Discoverable</a></li>
    <!-- tags if -->

  
    <li><a href="/posts/2026/07/25/modernizing-cider-completion.html">Modernizing CIDER's Completion</a></li>
    <!-- tags if -->

  
    <li><a href="/posts/2026/07/27/closing-the-find-usages-gap-in-cider.html">Closing the Find-Usages Gap in CIDER</a></li>
    <!-- tags if -->

    <!-- tags if -->

  
    <li><a href="/posts/2026/07/28/sharpening-ciders-debugging-tools.html">Sharpening CIDER's Debugging Tools</a></li>
    <!-- tags if -->

  
    <li><a href="/posts/2026/07/29/leveling-up-ciders-clojurescript-support.html">Leveling Up CIDER's ClojureScript Support</a></li>
    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->
 <!-- posts for -->
</ul>]]></content><author><name>Bozhidar Batsov</name></author><category term="posts" /><category term="CIDER 2.0" /><category term="Emacs" /><category term="Clojure" /><category term="ClojureScript" /><category term="CIDER" /><summary type="html"><![CDATA[Continuing the series on the notable changes in CIDER 2.0, let’s talk about ClojureScript - forever the trickier sibling in the CIDER family. I’ll start with a confession I’ve made before: I rarely use ClojureScript myself, which is a big part of why its support in CIDER has historically lagged behind Clojure’s. Every “State of CIDER” survey reminds me of this, usually in the comments section, occasionally in all caps. So in the 2.0 cycle I decided to stop feeling vaguely guilty about it and actually do something - across every layer of the stack: CIDER itself, cider-nrepl, and Piggieback. First, a strategic decision The most important ClojureScript change in CIDER 2.0 isn’t a feature - it’s a decision about what not to build. Some of CIDER’s most powerful tools (the debugger, enlighten, tracing, profiling) are deeply tied to JVM runtime introspection, and porting them to ClojureScript would be a massive effort with a poor cost/benefit ratio. Rather than keeping them in eternal “maybe someday” limbo, we’ve explicitly scoped them as Clojure-only and focused the actual work on the things cljs users hit every day: evaluation, testing, error reporting, and clear behavior everywhere else. That last part matters more than it sounds. Historically, invoking a JVM-only command in a ClojureScript REPL would fail in some confusing way - a cryptic error, a JVM-flavored result, or silence. Now the ops themselves report a clojure-only status, and CIDER tells you plainly that the command isn’t supported for ClojureScript. Knowing what a tool won’t do is half of trusting it. What actually got better The regular test commands (cider-test-run-ns-tests and friends) now work in ClojureScript REPLs, asynchronous cljs.test/async tests included. Previously CIDER just refused, and you were stuck evaluating (run-tests) by hand like an animal. Expanding your own macros (e.g. ones brought in via :refer-macros) used to silently echo the form back unexpanded - a bug filed all the way back in 2017. The compiler environment is now threaded to the analyzer properly, and it just works. cider-nrepl now resolves the ClojureScript compiler environment through a provider chain, with a dedicated shadow-cljs provider - so the static-analysis ops keep working in a shadow REPL that never loads Piggieback. The new cider-tap viewer works with ClojureScript too: a runtime helper buffers tapped values and the JVM side streams them to Emacs. (Tapped cljs values aren’t inspectable - they live in the JS runtime - but you see them as they happen.) ClojureScript stack frames now render their ns/fn properly instead of degrading to nil/nil, and unqualified core vars resolve against cljs.core rather than falling back to clojure.core (which quietly broke things like indentation metadata). A recent ClojureScript on the classpath (whose Closure compiler wants JDK 21+) no longer crashes cider-nrepl at startup on an older JDK - you get a Clojure-only session instead of no session. Piggieback itself got a round of bug fixes in the 0.6.x/0.7.0 releases - it’s easy to forget it exists (which is rather the point of it), but it powers most cljs REPLs CIDER talks to. The documentation kept pace too: the new full-stack Clojure + ClojureScript guide covers the two-REPLs-one-project setup that trips up nearly everyone, and the ClojureScript docs got a general refresh. An unexpected assist Fun aside: this is the area where AI coding agents helped me the most during the 2.0 cycle. My ClojureScript experience is limited, but between the excellent bug reports from the community and the ability to quickly prototype and test fixes against real shadow-cljs and figwheel setups, problems that had been “someone who knows cljs should look at this someday” for years finally got fixed. Make of that what you will. What’s next I keep pondering some form of “native” shadow-cljs support, given that shadow-cljs is what most ClojureScript users actually run these days. That’s still very much in the hammock phase, so don’t hold me to it - but the direction is clear: fewer moving parts, clearer errors, and honesty about what’s supported. If you’re a ClojureScript user, I’d genuinely love to hear how 2.0 feels in your daily work - the feedback loop is what keeps this improving. Keep hacking! Articles in the Series CIDER 2.0: Sky is the Limit Simplifying Session Management in CIDER Stepping Through Macros in CIDER Making CIDER More Discoverable Modernizing CIDER's Completion Closing the Find-Usages Gap in CIDER Sharpening CIDER's Debugging Tools Leveling Up CIDER's ClojureScript Support]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://metaredux.com/assets/og-image.png" /><media:content medium="image" url="https://metaredux.com/assets/og-image.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Sharpening CIDER’s Debugging Tools</title><link href="https://metaredux.com/posts/2026/07/28/sharpening-ciders-debugging-tools.html" rel="alternate" type="text/html" title="Sharpening CIDER’s Debugging Tools" /><published>2026-07-28T08:00:00+00:00</published><updated>2026-07-28T08:00:00+00:00</updated><id>https://metaredux.com/posts/2026/07/28/sharpening-ciders-debugging-tools</id><content type="html" xml:base="https://metaredux.com/posts/2026/07/28/sharpening-ciders-debugging-tools.html"><![CDATA[<p>The series on the notable changes in
<a href="/posts/2026/07/15/cider-2-0.html">CIDER 2.0</a> rolls on. This time: the
“what is my code <em>actually</em> doing?” toolbox - the debugger, tracing,
enlighten, and the new tap viewer. This was the part of the release I enjoyed
working on the most, and the part that needed the most love.</p>

<h2 id="the-debugger-dusted-off">The debugger, dusted off</h2>

<p>CIDER’s interactive debugger is one of its most impressive features and,
paradoxically, one of its least reliable ones. Instrumenting arbitrary Clojure
code is <em>hard</em> - the debugger rewrites your forms to capture locals at every
step, and the corner cases are endless. Over the 2.0 cycle (and the 0.62.x
releases of <code class="language-plaintext highlighter-rouge">cider-nrepl</code>) a whole family of long-standing instrumentation bugs
got fixed:</p>

<ul>
  <li>Record literals embedded in code survive instrumentation instead of being
quietly downgraded to plain maps - which used to break protocol dispatch in
anything that compiled routes or components into records (compojure users
know the pain).</li>
  <li><code class="language-plaintext highlighter-rouge">defrecord</code>/<code class="language-plaintext highlighter-rouge">deftype</code> inline methods no longer blow up with the infamous
<code class="language-plaintext highlighter-rouge">Unable to resolve symbol: STATE__</code> error - the instrumenter now sensibly
skips the method bodies, which compile to real JVM methods that can’t
capture debugger state. <code class="language-plaintext highlighter-rouge">#dbg</code> on a bare collection literal triggered the
same error; fixed too. And heavily destructured argument lists used to
crash instrumentation in their own special way - not anymore.</li>
  <li>A form too large to instrument (yes, that’s a JVM limitation - <code class="language-plaintext highlighter-rouge">Method code
too large!</code>) now degrades gracefully: CIDER retries without local capture and
tells you what happened, instead of surfacing a raw compiler error.</li>
  <li>Quitting a debug session uses nREPL’s interrupt machinery instead of the
deprecated <code class="language-plaintext highlighter-rouge">Thread.stop</code>, so it keeps working on modern JDKs where
<code class="language-plaintext highlighter-rouge">Thread.stop</code> is simply gone.</li>
</ul>

<p>The UX got attention too. Quitting the debugger with <code class="language-plaintext highlighter-rouge">q</code> finally restores point
to where you started the session - a request filed in
<a href="https://github.com/clojure-emacs/cider/issues/1595">2016</a> - instead of
stranding you at the last breakpoint. The force-step-out key works again. And
all the debugger’s single-key commands are now proper named commands with a
transient menu (<code class="language-plaintext highlighter-rouge">?</code>) listing them, so you’re never stuck trying to remember
whether locals was <code class="language-plaintext highlighter-rouge">l</code> or <code class="language-plaintext highlighter-rouge">L</code>.</p>

<h2 id="tracing-grew-a-home">Tracing grew a home</h2>

<p><code class="language-plaintext highlighter-rouge">clojure.tools.trace</code>-style tracing has been in CIDER forever, but the output
was always interleaved into the REPL, where it fought with your actual work.
CIDER 2.0 gives traces a dedicated, live-streaming <code class="language-plaintext highlighter-rouge">*cider-trace*</code> buffer:</p>

<p><img src="/assets/images/cider-trace-buffer.png" alt="The *cider-trace* buffer showing a nested call tree with return values" /></p>

<p>Calls fold and unfold (<code class="language-plaintext highlighter-rouge">TAB</code>, or <code class="language-plaintext highlighter-rouge">F</code>/<code class="language-plaintext highlighter-rouge">U</code> for everything at once), <code class="language-plaintext highlighter-rouge">n</code>/<code class="language-plaintext highlighter-rouge">p</code> move
between calls, and <code class="language-plaintext highlighter-rouge">.</code> jumps to a function’s definition. <code class="language-plaintext highlighter-rouge">cider-list-traced</code>
answers the eternal “wait, what did I even trace?”, and <code class="language-plaintext highlighter-rouge">cider-untrace-all</code>
cleans the slate.</p>

<h2 id="enlighten-back-from-the-dead">Enlighten, back from the dead</h2>

<p><a href="https://docs.cider.mx/cider/debugging/enlighten.html">Enlighten</a> - the mode
that displays the values of locals inline as your code runs - has been in
“experimental” limbo since 2016. It finally got a proper overhaul: a real test
suite, fixes for the same record/deftype instrumentation bugs as the debugger
(they share machinery), and - importantly - manners. You can now enlighten a
single form with <code class="language-plaintext highlighter-rouge">cider-enlighten-defun-at-point</code> instead of flipping a global
mode, and <code class="language-plaintext highlighter-rouge">cider-enlighten-stop</code> turns everything off at once, rather than
making you re-evaluate every function in penance.</p>

<p>Every local and every intermediate result, right there in the buffer:</p>

<p><img src="/assets/images/cider-enlighten.png" alt="Enlighten showing argument and return values inline in the source" /></p>

<h2 id="tap-into-your-programs">Tap into your programs</h2>

<p>New in 2.0: <code class="language-plaintext highlighter-rouge">cider-tap</code>, a buffer that streams every value sent to <code class="language-plaintext highlighter-rouge">tap&gt;</code> and
lets you crack any of them open in the inspector with <code class="language-plaintext highlighter-rouge">RET</code>. <code class="language-plaintext highlighter-rouge">tap&gt;</code> has quietly
become the Clojure community’s favorite debugging primitive, and now you don’t
need an external tool like Portal or Reveal for the basic workflow - though
those remain great if you want more. (ClojureScript taps stream too; they’re
just not inspectable, since the values live in the JS runtime.)</p>

<p>It’s <code class="language-plaintext highlighter-rouge">println</code> debugging, minus the println guilt.</p>

<h2 id="the-connective-tissue">The connective tissue</h2>

<p>A few related quality-of-life items round out the picture: stack frames for
top-level anonymous functions jump to their actual source instead of
<code class="language-plaintext highlighter-rouge">clojure.core/fn</code> (a bug from
<a href="https://github.com/clojure-emacs/cider/issues/3157">2020</a>), ClojureScript
frames render their <code class="language-plaintext highlighter-rouge">ns/fn</code> properly, and the macroexpansion tooling - a
debugging tool in its own right - got a full makeover that deserves (and will
get) its own article.</p>

<p>None of these tools is new. That’s rather the point: the 2.0 debugging story
is mostly the existing tools becoming trustworthy. A debugger you don’t trust
is worse than no debugger at all.</p>

<p>The <a href="https://docs.cider.mx/cider/debugging/debugger.html">debugging docs</a> cover
everything in detail. Keep hacking!</p>

<h2>Articles in the Series</h2>

<ul>

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

  
    <li><a href="/posts/2026/07/15/cider-2-0.html">CIDER 2.0: Sky is the Limit</a></li>
    <!-- tags if -->

  
    <li><a href="/posts/2026/07/16/simplifying-session-management-in-cider.html">Simplifying Session Management in CIDER</a></li>
    <!-- tags if -->

    <!-- tags if -->

  
    <li><a href="/posts/2026/07/17/stepping-through-macros-in-cider.html">Stepping Through Macros in CIDER</a></li>
    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

  
    <li><a href="/posts/2026/07/23/making-cider-more-discoverable.html">Making CIDER More Discoverable</a></li>
    <!-- tags if -->

  
    <li><a href="/posts/2026/07/25/modernizing-cider-completion.html">Modernizing CIDER's Completion</a></li>
    <!-- tags if -->

  
    <li><a href="/posts/2026/07/27/closing-the-find-usages-gap-in-cider.html">Closing the Find-Usages Gap in CIDER</a></li>
    <!-- tags if -->

    <!-- tags if -->

  
    <li><a href="/posts/2026/07/28/sharpening-ciders-debugging-tools.html">Sharpening CIDER's Debugging Tools</a></li>
    <!-- tags if -->

  
    <li><a href="/posts/2026/07/29/leveling-up-ciders-clojurescript-support.html">Leveling Up CIDER's ClojureScript Support</a></li>
    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->
 <!-- posts for -->
</ul>]]></content><author><name>Bozhidar Batsov</name></author><category term="posts" /><category term="CIDER 2.0" /><category term="Emacs" /><category term="Clojure" /><category term="CIDER" /><summary type="html"><![CDATA[The series on the notable changes in CIDER 2.0 rolls on. This time: the “what is my code actually doing?” toolbox - the debugger, tracing, enlighten, and the new tap viewer. This was the part of the release I enjoyed working on the most, and the part that needed the most love. The debugger, dusted off CIDER’s interactive debugger is one of its most impressive features and, paradoxically, one of its least reliable ones. Instrumenting arbitrary Clojure code is hard - the debugger rewrites your forms to capture locals at every step, and the corner cases are endless. Over the 2.0 cycle (and the 0.62.x releases of cider-nrepl) a whole family of long-standing instrumentation bugs got fixed: Record literals embedded in code survive instrumentation instead of being quietly downgraded to plain maps - which used to break protocol dispatch in anything that compiled routes or components into records (compojure users know the pain). defrecord/deftype inline methods no longer blow up with the infamous Unable to resolve symbol: STATE__ error - the instrumenter now sensibly skips the method bodies, which compile to real JVM methods that can’t capture debugger state. #dbg on a bare collection literal triggered the same error; fixed too. And heavily destructured argument lists used to crash instrumentation in their own special way - not anymore. A form too large to instrument (yes, that’s a JVM limitation - Method code too large!) now degrades gracefully: CIDER retries without local capture and tells you what happened, instead of surfacing a raw compiler error. Quitting a debug session uses nREPL’s interrupt machinery instead of the deprecated Thread.stop, so it keeps working on modern JDKs where Thread.stop is simply gone. The UX got attention too. Quitting the debugger with q finally restores point to where you started the session - a request filed in 2016 - instead of stranding you at the last breakpoint. The force-step-out key works again. And all the debugger’s single-key commands are now proper named commands with a transient menu (?) listing them, so you’re never stuck trying to remember whether locals was l or L. Tracing grew a home clojure.tools.trace-style tracing has been in CIDER forever, but the output was always interleaved into the REPL, where it fought with your actual work. CIDER 2.0 gives traces a dedicated, live-streaming *cider-trace* buffer: Calls fold and unfold (TAB, or F/U for everything at once), n/p move between calls, and . jumps to a function’s definition. cider-list-traced answers the eternal “wait, what did I even trace?”, and cider-untrace-all cleans the slate. Enlighten, back from the dead Enlighten - the mode that displays the values of locals inline as your code runs - has been in “experimental” limbo since 2016. It finally got a proper overhaul: a real test suite, fixes for the same record/deftype instrumentation bugs as the debugger (they share machinery), and - importantly - manners. You can now enlighten a single form with cider-enlighten-defun-at-point instead of flipping a global mode, and cider-enlighten-stop turns everything off at once, rather than making you re-evaluate every function in penance. Every local and every intermediate result, right there in the buffer: Tap into your programs New in 2.0: cider-tap, a buffer that streams every value sent to tap&gt; and lets you crack any of them open in the inspector with RET. tap&gt; has quietly become the Clojure community’s favorite debugging primitive, and now you don’t need an external tool like Portal or Reveal for the basic workflow - though those remain great if you want more. (ClojureScript taps stream too; they’re just not inspectable, since the values live in the JS runtime.) It’s println debugging, minus the println guilt. The connective tissue A few related quality-of-life items round out the picture: stack frames for top-level anonymous functions jump to their actual source instead of clojure.core/fn (a bug from 2020), ClojureScript frames render their ns/fn properly, and the macroexpansion tooling - a debugging tool in its own right - got a full makeover that deserves (and will get) its own article. None of these tools is new. That’s rather the point: the 2.0 debugging story is mostly the existing tools becoming trustworthy. A debugger you don’t trust is worse than no debugger at all. The debugging docs cover everything in detail. Keep hacking! Articles in the Series CIDER 2.0: Sky is the Limit Simplifying Session Management in CIDER Stepping Through Macros in CIDER Making CIDER More Discoverable Modernizing CIDER's Completion Closing the Find-Usages Gap in CIDER Sharpening CIDER's Debugging Tools Leveling Up CIDER's ClojureScript Support]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://metaredux.com/assets/og-image.png" /><media:content medium="image" url="https://metaredux.com/assets/og-image.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Projectile 3.3</title><link href="https://metaredux.com/posts/2026/07/27/projectile-3-3.html" rel="alternate" type="text/html" title="Projectile 3.3" /><published>2026-07-27T08:15:00+00:00</published><updated>2026-07-27T08:15:00+00:00</updated><id>https://metaredux.com/posts/2026/07/27/projectile-3-3</id><content type="html" xml:base="https://metaredux.com/posts/2026/07/27/projectile-3-3.html"><![CDATA[<p><a href="https://github.com/bbatsov/projectile/releases/tag/v3.3.0">Projectile 3.3</a> is out! That’s
the fourth release this month, which probably tells you something about how much fun I’ve
been having with Projectile lately.</p>

<p>This one is mostly about a single theme - Projectile knowing more about your project
without you having to tell it anything.</p>

<!--more-->

<h2 id="tasks-you-never-configured">Tasks you never configured</h2>

<p>Projectile has had named tasks for a while now - you put an alist in <code class="language-plaintext highlighter-rouge">projectile-tasks</code>
(or in your project’s <code class="language-plaintext highlighter-rouge">.dir-locals.el</code>) and <code class="language-plaintext highlighter-rouge">projectile-run-task</code> (<code class="language-plaintext highlighter-rouge">s-p c x</code>) offers
them with completion. Useful, but there was a catch that always bugged me: the variable
starts out empty, so the command did precisely nothing until you sat down and filled it in.</p>

<p>Meanwhile every project I work on already has its tasks written down somewhere. The npm
scripts are in <code class="language-plaintext highlighter-rouge">package.json</code>. The Makefile targets are in the Makefile. So now Projectile
just reads them:</p>

<p><img src="/assets/images/projectile-discovered-tasks.png" alt="The projectile-run-task prompt listing npm scripts and Makefile targets discovered in the project" /></p>

<p>That’s a fresh checkout with zero Projectile configuration. Out of the box it knows about
npm scripts (running them through whichever package manager your lock file implies - npm,
yarn, pnpm or bun), Deno tasks, Composer scripts, <code class="language-plaintext highlighter-rouge">just</code> recipes, go-task tasks and Makefile
targets. The tool name is part of the task name, so <code class="language-plaintext highlighter-rouge">npm:build</code> and <code class="language-plaintext highlighter-rouge">make:build</code> can happily
coexist and you can see at a glance where something came from.</p>

<p>If you don’t want this, <code class="language-plaintext highlighter-rouge">projectile-discover-tasks</code> turns it off. If you want more of it,
<code class="language-plaintext highlighter-rouge">projectile-task-providers</code> is just a list of functions that take a project root and return
an alist - adding support for your favorite task runner is a few lines.</p>

<h2 id="a-lot-more-project-types">A lot more project types</h2>

<p>Projectile ships with a registry of project types, and I finally sat down and went through
it properly. The result is 34 new types.</p>

<p>The one that surprised me most was that a <code class="language-plaintext highlighter-rouge">package.json</code> without a lock file next to it
matched nothing at all - such a project came out as <code class="language-plaintext highlighter-rouge">generic</code>, with no compile or test
command. That can’t have been a rare situation. Also missing: Bun, Deno, uv (which has
pretty much taken over new Python projects), plain Composer, Laravel, Xcode, Flutter,
Terraform, Pulumi, Helm, Ansible, <code class="language-plaintext highlighter-rouge">just</code>, mise, Gleam, Babashka, scala-cli, Godot,
PlatformIO, and the static site generators (Hugo, Jekyll, Zola, MkDocs, Quarto).</p>

<p>Going through the registry also turned up three bugs that had been sitting there quietly:</p>

<ul>
  <li>The <code class="language-plaintext highlighter-rouge">angular</code> type could never match anything. It listed two markers, <code class="language-plaintext highlighter-rouge">angular.json</code> and
<code class="language-plaintext highlighter-rouge">.angular-cli.json</code>, and marker lists are ANDed - but a project has one or the other,
never both. So the type had been dead since the day <code class="language-plaintext highlighter-rouge">angular.json</code> was added.</li>
  <li><code class="language-plaintext highlighter-rouge">pyproject.toml</code> was checked before <code class="language-plaintext highlighter-rouge">django</code>, <code class="language-plaintext highlighter-rouge">python-poetry</code>, <code class="language-plaintext highlighter-rouge">python-pipenv</code> and
<code class="language-plaintext highlighter-rouge">python-tox</code>. Since just about every Python project has a <code class="language-plaintext highlighter-rouge">pyproject.toml</code> these days,
those four types effectively never matched. A Django project would come out as
<code class="language-plaintext highlighter-rouge">python-toml</code> and lose its file kinds along with its commands.</li>
  <li><code class="language-plaintext highlighter-rouge">php-symfony</code> required an <code class="language-plaintext highlighter-rouge">app</code> directory, which Symfony dropped in version 3, and a
<code class="language-plaintext highlighter-rouge">vendor</code> directory, which only exists after someone runs composer. Modern Symfony
projects weren’t detected at all.</li>
</ul>

<p>I’ve also brought the stale markers up to date (Bazel’s <code class="language-plaintext highlighter-rouge">MODULE.bazel</code>, Gradle’s Kotlin
DSL, Zig’s <code class="language-plaintext highlighter-rouge">build.zig</code>) and fixed a pile of lifecycle commands that had rotted - Symfony’s
console moved to <code class="language-plaintext highlighter-rouge">bin/</code> years ago, the Dart CLI absorbed <code class="language-plaintext highlighter-rouge">pub</code>, <code class="language-plaintext highlighter-rouge">setup.py build</code> is
deprecated by the PyPA, and poetry projects run pytest rather than unittest discovery.</p>

<p>There’s a new <code class="language-plaintext highlighter-rouge">(:any "file1" "file2")</code> form for markers, which is what made most of this
expressible as plain data rather than yet another predicate function.<sup id="fnref:1" role="doc-noteref"><a href="#fn:1" class="footnote" rel="footnote">1</a></sup></p>

<h2 id="monorepos">Monorepos</h2>

<p>If you work in a monorepo you know the problem: the repository is one project as far as
git (and therefore Projectile) is concerned, but you’re usually working on one piece of it,
and building or testing the whole thing is a waste of time.</p>

<p>Projectile now understands that a directory holding a manifest of its own is a <em>subproject</em>.
<code class="language-plaintext highlighter-rouge">projectile-find-file-in-subproject</code> (<code class="language-plaintext highlighter-rouge">s-p c m f</code>) asks which one you want and then
scopes file completion to it:</p>

<p><img src="/assets/images/projectile-find-file-in-subproject.png" alt="The Subproject prompt listing packages/ui, services/api and services/web" /></p>

<p>And every lifecycle command has a subproject variant now - <code class="language-plaintext highlighter-rouge">s-p c m c</code> compiles, <code class="language-plaintext highlighter-rouge">s-p c m t</code>
tests, <code class="language-plaintext highlighter-rouge">s-p c m r</code> runs, and so on. They use the project’s own command and simply run it in
the nearest subproject, which is exactly what workspace-aware tools like Cargo, npm and
Maven need in order to scope their work.</p>

<p>There were subproject compile and test commands before this release, but they only looked
for the marker of the project’s <em>own</em> type, which meant they were useless in a polyglot
repository - a Rust crate sitting under a <code class="language-plaintext highlighter-rouge">package.json</code> project was invisible to them. Now
the markers come from every registered project type, so it works regardless of what the repo
looks like from the top.</p>

<h2 id="two-commands-for-looking-at-a-project">Two commands for looking at a project</h2>

<p><code class="language-plaintext highlighter-rouge">projectile-dashboard</code> (<code class="language-plaintext highlighter-rouge">s-p P</code>) summarizes the project you’re in:</p>

<p><img src="/assets/images/projectile-dashboard.png" alt="The Projectile dashboard showing project info, version control status, recent files and tasks" /></p>

<p>Everything in there is a button, so you can jump to a file, run a task or kick off a build
without leaving the buffer. It never indexes the project and only queries git when the
project is a local git repo, which makes it cheap enough to use as your
<code class="language-plaintext highlighter-rouge">projectile-switch-project-action</code> - which is exactly what I do now.</p>

<p>The other one is <code class="language-plaintext highlighter-rouge">projectile-doctor</code> (<code class="language-plaintext highlighter-rouge">s-p H</code>), which explains how Projectile sees the
current project:</p>

<p><img src="/assets/images/projectile-doctor.png" alt="The Projectile doctor report showing project root, type, indexing method and available tools" /></p>

<p>Root, which detection function found it and on which marker, the type and its marker, the
indexing method and the exact command that will run, which external tools are available, the
cache state, the effective ignore rules - and then a list of findings, each either <code class="language-plaintext highlighter-rouge">ok</code> or a
concrete suggestion. It’s plain text, meant to be pasted into a bug report. Selfishly, I’m
hoping this saves us both some back-and-forth in the issue tracker.</p>

<h2 id="odds-and-ends">Odds and ends</h2>

<p>A few smaller things worth knowing about:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">projectile-todos</code> (<code class="language-plaintext highlighter-rouge">s-p s t</code>) collects the project’s <code class="language-plaintext highlighter-rouge">TODO</code>/<code class="language-plaintext highlighter-rouge">FIXME</code> annotations into
the reviewable search buffer.</li>
  <li>Project-scoped bookmarks - <code class="language-plaintext highlighter-rouge">s-p B s</code>, <code class="language-plaintext highlighter-rouge">s-p B j</code>, <code class="language-plaintext highlighter-rouge">s-p B d</code>. They’re plain Emacs bookmarks,
Projectile just scopes the completion to the current project.</li>
  <li><code class="language-plaintext highlighter-rouge">projectile-replace-undo</code> (<code class="language-plaintext highlighter-rouge">s-p u</code>) reverts the last replace you applied from the
review buffer, and it’s careful about it - a file whose text has changed since is reported
and left alone.</li>
  <li><code class="language-plaintext highlighter-rouge">projectile-per-command-compilation-buffer</code> gives compile, test and run separate
compilation buffers, so running the tests no longer discards your build output.</li>
  <li>An optional Embark and Marginalia integration, wired up with <code class="language-plaintext highlighter-rouge">with-eval-after-load</code> so
neither package becomes a dependency.</li>
</ul>

<h2 id="bug-fixes">Bug fixes</h2>

<p>Three worth calling out.</p>

<p>The first is embarrassing and recent: with asynchronous indexing enabled, <code class="language-plaintext highlighter-rouge">projectile-find-file</code>
could show “Projectile is indexing” and spin forever. Projectile was waiting on the indexing
process’s <em>sentinel</em>, and Emacs doesn’t actually promise to run one while a command sits
waiting on the process. It now waits on the process itself and collects the output on its
own if the sentinel doesn’t show up.<sup id="fnref:2" role="doc-noteref"><a href="#fn:2" class="footnote" rel="footnote">2</a></sup> Thanks to Mike Crowe for a bug report with enough
detail in it (<code class="language-plaintext highlighter-rouge">strace</code> output included) that I could work backwards to the cause.</p>

<p>The second: in CMake projects, editing the compile command at the prompt didn’t stick, and
you’d get the default offered again on the next run. That was a side effect of a fix from
3.2 that made function-valued commands re-resolve on every run so the preset picker could
prompt again. It threw away your edit along with the cached command. Both behaviors work
now - your edit is remembered, the picker still gets to prompt.</p>

<p>The third one has been open since 2016. If you opened a file that git ignores, Projectile
would happily add it to the file cache, and it would then keep showing up in
<code class="language-plaintext highlighter-rouge">projectile-find-file</code> even though indexing had correctly left it out. Projectile’s own
ignore rules simply don’t know anything about <code class="language-plaintext highlighter-rouge">.gitignore</code>, so it now asks git directly
before caching a file it hasn’t seen before.</p>

<h2 id="upgrade-notes">Upgrade notes</h2>

<p>A few changes might alter what you see, so it’s worth knowing about them before you upgrade:</p>

<ul>
  <li>Alien indexing now honors Projectile’s ignore rules, which it used to skip entirely. This
means alien projects will list <em>fewer</em> files than before. Set
<code class="language-plaintext highlighter-rouge">projectile-alien-honors-ignores</code> to <code class="language-plaintext highlighter-rouge">nil</code> if you want the old behavior.</li>
  <li>The ignore configuration speaks gitignore patterns everywhere now, matched the same way by
every indexing method. Mostly this just works, but a leading <code class="language-plaintext highlighter-rouge">*</code> used to mean “at any
depth” and is now a plain wildcard, so <code class="language-plaintext highlighter-rouge">*node_modules</code> should become <code class="language-plaintext highlighter-rouge">node_modules</code>.</li>
  <li><code class="language-plaintext highlighter-rouge">projectile-globally-ignored-directories</code> now includes the build and dependency
directories of the common ecosystems - <code class="language-plaintext highlighter-rouge">node_modules</code>, <code class="language-plaintext highlighter-rouge">target</code>, <code class="language-plaintext highlighter-rouge">__pycache__</code>, <code class="language-plaintext highlighter-rouge">.venv</code>,
<code class="language-plaintext highlighter-rouge">.next</code>, <code class="language-plaintext highlighter-rouge">.terraform</code> and a couple of dozen more. Directories that projects sometimes
do commit (<code class="language-plaintext highlighter-rouge">vendor</code>, <code class="language-plaintext highlighter-rouge">dist</code>, <code class="language-plaintext highlighter-rouge">public</code>, <code class="language-plaintext highlighter-rouge">build</code>) are deliberately not on the list.</li>
</ul>

<p>The full changelog is <a href="https://github.com/bbatsov/projectile/blob/master/CHANGELOG.md">here</a>,
and the manual is at <a href="https://docs.projectile.mx/">docs.projectile.mx</a>.</p>

<p>That’s all I have for you today. Keep hacking!</p>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1" role="doc-endnote">
      <p>Gradle is a good example - <code class="language-plaintext highlighter-rouge">build.gradle</code>, <code class="language-plaintext highlighter-rouge">build.gradle.kts</code>, <code class="language-plaintext highlighter-rouge">settings.gradle</code> and <code class="language-plaintext highlighter-rouge">settings.gradle.kts</code> all mark a Gradle project, and a project will have some of them but not all. <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:2" role="doc-endnote">
      <p>See <a href="https://github.com/bbatsov/projectile/pull/2124">https://github.com/bbatsov/projectile/pull/2124</a>. <a href="#fnref:2" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Bozhidar Batsov</name></author><category term="posts" /><category term="Emacs" /><category term="Projectile" /><summary type="html"><![CDATA[Projectile 3.3 is out! That’s the fourth release this month, which probably tells you something about how much fun I’ve been having with Projectile lately. This one is mostly about a single theme - Projectile knowing more about your project without you having to tell it anything.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://metaredux.com/assets/og-image.png" /><media:content medium="image" url="https://metaredux.com/assets/og-image.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Closing the Find-Usages Gap in CIDER</title><link href="https://metaredux.com/posts/2026/07/27/closing-the-find-usages-gap-in-cider.html" rel="alternate" type="text/html" title="Closing the Find-Usages Gap in CIDER" /><published>2026-07-27T07:30:00+00:00</published><updated>2026-07-27T07:30:00+00:00</updated><id>https://metaredux.com/posts/2026/07/27/closing-the-find-usages-gap-in-cider</id><content type="html" xml:base="https://metaredux.com/posts/2026/07/27/closing-the-find-usages-gap-in-cider.html"><![CDATA[<p>Next up in the series on the notable changes in
<a href="/posts/2026/07/15/cider-2-0.html">CIDER 2.0</a>: cross-references. Or, as
most people call the feature, “find usages” - for years the most commonly
cited reason to run <a href="https://clojure-lsp.io/">clojure-lsp</a> alongside (or
instead of) CIDER. Let’s talk about why that gap existed and how we finally
closed it.</p>

<h2 id="why-runtime-xref-wasnt-enough">Why runtime xref wasn’t enough</h2>

<p>CIDER has had <em>runtime</em> cross-referencing for a while: the <code class="language-plaintext highlighter-rouge">cider/fn-refs</code> op
walks the loaded vars in your REPL and reports which functions reference the
one at point. It’s a genuinely cool trick - the REPL literally knows your
program - but as a “find usages” answer it has three structural problems:</p>

<ul>
  <li>It only sees <strong>loaded</strong> code. Namespaces you haven’t required yet - often
most of the codebase - are invisible.</li>
  <li>It reports <em>functions</em>, not <em>occurrences</em>. Each hit points at the caller’s
definition, not the exact call site, and a function that calls yours three
times shows up once.</li>
  <li>It’s JVM-only, so ClojureScript users got nothing.</li>
</ul>

<p>clojure-lsp, by contrast, builds a static index of your whole project with
clj-kondo’s analyzer and answers instantly, loaded or not. For
occurrence-oriented questions (“show me every place this is used, so I can
change all of them”), static analysis is simply the right tool. No amount of
runtime cleverness fixes “the code isn’t loaded”.</p>

<h2 id="the-fix-search-the-source">The fix: search the source</h2>

<p>So CIDER 2.0 does the obvious thing we should have done years ago:
<code class="language-plaintext highlighter-rouge">xref-find-references</code> (<code class="language-plaintext highlighter-rouge">M-?</code>) now finds references by <strong>searching the
project’s source files</strong> on disk. Unloaded code, <code class="language-plaintext highlighter-rouge">cljs</code> files, commented-out
drafts - if the name occurs in the project, you’ll see the exact occurrence,
in the standard xref UI you already use for everything else in Emacs. To
borrow the franchise that has been handing programmers debugging metaphors
for over two decades now: the runtime is the Matrix, a tidy compiled illusion
of your program, and to see every place a thing is really used you sometimes
have to unplug and look at the source itself.<sup id="fnref:matrix" role="doc-noteref"><a href="#fn:matrix" class="footnote" rel="footnote">1</a></sup></p>

<p>Here’s the difference in one picture - the same query on
<code class="language-plaintext highlighter-rouge">orchard.misc/require-and-resolve</code>, first in runtime mode, then in source
mode:</p>

<p><img src="/assets/images/cider-xref-runtime-vs-source.gif" alt="Find-usages of orchard.misc/require-and-resolve: the runtime search returns only the loaded callers, one per calling function, while the source search finds every occurrence across the project - including the alias-qualified uses in other namespaces and a cljc file the REPL never loaded" /></p>

<p>The runtime knows about three callers - and points you at each <em>caller’s</em>
definition. The source scan turns up all ten actual occurrences, across five
files, including the ones written as <code class="language-plaintext highlighter-rouge">misc/require-and-resolve</code> in namespaces
the REPL never loaded. That’s the gap, in one screenshot.</p>

<p>Now, “search the source” makes it sound like a <code class="language-plaintext highlighter-rouge">grep</code>, and I want to be clear
that it isn’t a dumb one. Say you’re chasing <code class="language-plaintext highlighter-rouge">orchard.misc/require-and-resolve</code>.
The search runs in three stages:</p>

<ol>
  <li>First CIDER asks the REPL to resolve the symbol at point to its fully
qualified name, <code class="language-plaintext highlighter-rouge">orchard.misc/require-and-resolve</code>. The REPL is right there
on the other end of the wire, so why guess when you can ask?</li>
  <li>A fast first pass (<code class="language-plaintext highlighter-rouge">ripgrep</code>, via Emacs’ own <code class="language-plaintext highlighter-rouge">xref-matches-in-files</code>) finds
every file that so much as mentions <code class="language-plaintext highlighter-rouge">require-and-resolve</code>, purely to narrow
the field.</li>
  <li>Then the Clojure-aware part. For each of those files, CIDER reads its
<code class="language-plaintext highlighter-rouge">(ns ...)</code> form to learn <em>how</em> that file pulls in <code class="language-plaintext highlighter-rouge">orchard.misc</code> - aliased
as <code class="language-plaintext highlighter-rouge">[orchard.misc :as misc]</code>, brought in with <code class="language-plaintext highlighter-rouge">:refer [require-and-resolve]</code>,
or is this <code class="language-plaintext highlighter-rouge">orchard.misc</code> itself? - and builds a regexp that matches only
the forms that file could legitimately use: the qualified
<code class="language-plaintext highlighter-rouge">orchard.misc/require-and-resolve</code>, the aliased <code class="language-plaintext highlighter-rouge">misc/require-and-resolve</code>,
or a bare <code class="language-plaintext highlighter-rouge">require-and-resolve</code> where the namespace declaration makes that
valid. The requires inside the <code class="language-plaintext highlighter-rouge">ns</code> form are excluded, so the import line
doesn’t show up as a “usage”.<sup id="fnref:fix" role="doc-noteref"><a href="#fn:fix" class="footnote" rel="footnote">2</a></sup></li>
</ol>

<p>Is any of this as smart as clj-kondo’s full analysis? No - it’s ultimately a
syntactic search, so an identically named var in another namespace can still
sneak through as a false positive. But because it’s ns-aware rather than a
blind text match, a bare <code class="language-plaintext highlighter-rouge">require-and-resolve</code> in some file that never requires
<code class="language-plaintext highlighter-rouge">orchard.misc</code> (and has a <code class="language-plaintext highlighter-rouge">require-and-resolve</code> of its own) won’t be mistaken
for yours. For the daily “where is this used?” question it turns out to be
remarkably close to the real thing in practice, it requires zero extra
infrastructure, and it composes with what only CIDER has: the running REPL.</p>

<p>That composition is configurable via <code class="language-plaintext highlighter-rouge">cider-xref-references-mode</code>:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">source</code> (the default) - occurrences from the project’s files.</li>
  <li><code class="language-plaintext highlighter-rouge">runtime</code> - the historical loaded-vars behavior.</li>
  <li><code class="language-plaintext highlighter-rouge">both</code> - source occurrences first, plus the runtime hits the scan can’t see.
And there <em>are</em> such hits: references generated by macro expansion leave no
textual trace in your source, but the runtime knows about them. Static
analysis can’t ever tell you those; your REPL can.</li>
</ul>

<p>(There’s also <code class="language-plaintext highlighter-rouge">cider-xref-fn-refs-in-source</code>, <code class="language-plaintext highlighter-rouge">C-c C-? s</code>, when you want the
source search explicitly, and outside a project the source mode gracefully
falls back to the runtime search.)</p>

<h2 id="beyond-find-usages-the-who--family">Beyond find usages: the who-* family</h2>

<p>While closing the gap, we went further and built out a whole family of
SLIME-inspired cross-referencing commands under <code class="language-plaintext highlighter-rouge">C-c C-w</code>, most of them
rendered as expandable trees:</p>

<ul>
  <li>
    <p><code class="language-plaintext highlighter-rouge">cider-who-calls</code> / <code class="language-plaintext highlighter-rouge">cider-who-is-called</code> - the call graph, upward and
downward. Expand a caller to see <em>its</em> callers; spelunk as deep as you like:</p>

    <p><img src="/assets/images/cider-who-calls-tree.png" alt="The cider-who-calls tree, expanded two levels up the call graph" /></p>
  </li>
  <li><code class="language-plaintext highlighter-rouge">cider-who-implements</code> - a protocol’s implementing types (inline
<code class="language-plaintext highlighter-rouge">defrecord</code>/<code class="language-plaintext highlighter-rouge">deftype</code> implementations included) or a multimethod’s dispatch
values, each jumping to the implementation’s source. Multimethods are a nice
case study in hybrid thinking: the method functions carry no source metadata
at runtime, so CIDER locates the <code class="language-plaintext highlighter-rouge">defmethod</code> forms by - you guessed it -
searching the source.</li>
  <li><code class="language-plaintext highlighter-rouge">cider-type-protocols</code> / <code class="language-plaintext highlighter-rouge">cider-protocols-with-method</code> - the reverse
lookups: what does this type implement, and which protocols declare this
method?</li>
  <li><code class="language-plaintext highlighter-rouge">cider-who-macroexpands</code> - a macro’s use sites, found via source search,
because macro invocations are expanded away at compile time and the runtime
literally cannot see them.</li>
</ul>

<p>Much of this is powered by new ops in <code class="language-plaintext highlighter-rouge">cider-nrepl</code> (and
<a href="https://github.com/clojure-emacs/orchard">Orchard</a> underneath), and much of
the inspiration came straight from SLIME and swank-clojure, which offered
<code class="language-plaintext highlighter-rouge">who-calls</code> back when Clojure itself was barely out of the crib. And here’s
the part I love: the whole “go read the source instead of trusting the
runtime” instinct was already there in swank-clojure’s implementation. Its
<code class="language-plaintext highlighter-rouge">who-calls</code> would find candidate callers among the loaded vars, sure, but then
it went and <em>read the actual source form of each one off disk</em> and walked the
parsed code looking for your symbol, rather than believing whatever the
compiled runtime claimed. It was still anchored to loaded code - it never
scanned the whole project the way CIDER 2.0 does - but the core idea, that the
source on disk is the ground truth and the runtime is just a convenient
approximation, predates this release by about fifteen years. Good ideas don’t
expire. Sometimes nothing beats revisiting the classics.<sup id="fnref:source" role="doc-noteref"><a href="#fn:source" class="footnote" rel="footnote">3</a></sup></p>

<h2 id="so-do-you-still-need-clojure-lsp">So do you still need clojure-lsp?</h2>

<p>If you were running clojure-lsp <em>primarily</em> for find-usages - the most common
answer I heard when I asked - then CIDER now covers you out of the box. If you
use it for project-wide renames, unused-var linting, or editing without a REPL,
carry on; those are real strengths of static analysis and CIDER doesn’t try to
replicate them. The two continue to
<a href="https://docs.cider.mx/cider/config/lsp.html">work fine side by side</a>, and the
new async eldoc even yields politely so LSP-provided docs can compose with
CIDER’s.</p>

<p>My goal was never to “beat” clojure-lsp - it was to make a freshly installed
CIDER answer the questions every Clojure programmer asks a dozen times a day,
with no extra moving parts, and with the one advantage nobody else has: a live
runtime on the other end of the wire.</p>

<p>The full story is in the
<a href="https://docs.cider.mx/cider/usage/navigation.html">navigation docs</a>. Keep
hacking!</p>

<h2>Articles in the Series</h2>

<ul>

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

  
    <li><a href="/posts/2026/07/15/cider-2-0.html">CIDER 2.0: Sky is the Limit</a></li>
    <!-- tags if -->

  
    <li><a href="/posts/2026/07/16/simplifying-session-management-in-cider.html">Simplifying Session Management in CIDER</a></li>
    <!-- tags if -->

    <!-- tags if -->

  
    <li><a href="/posts/2026/07/17/stepping-through-macros-in-cider.html">Stepping Through Macros in CIDER</a></li>
    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

  
    <li><a href="/posts/2026/07/23/making-cider-more-discoverable.html">Making CIDER More Discoverable</a></li>
    <!-- tags if -->

  
    <li><a href="/posts/2026/07/25/modernizing-cider-completion.html">Modernizing CIDER's Completion</a></li>
    <!-- tags if -->

  
    <li><a href="/posts/2026/07/27/closing-the-find-usages-gap-in-cider.html">Closing the Find-Usages Gap in CIDER</a></li>
    <!-- tags if -->

    <!-- tags if -->

  
    <li><a href="/posts/2026/07/28/sharpening-ciders-debugging-tools.html">Sharpening CIDER's Debugging Tools</a></li>
    <!-- tags if -->

  
    <li><a href="/posts/2026/07/29/leveling-up-ciders-clojurescript-support.html">Leveling Up CIDER's ClojureScript Support</a></li>
    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->

    <!-- tags if -->
 <!-- posts for -->
</ul>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:matrix" role="doc-endnote">
      <p>As Morpheus puts it: “Unfortunately, no one can be told what the
Matrix is. You have to see it for yourself.” Same with find-usages,
really - I can tell you a var is used in seven places, but until you’ve
seen the actual call sites you don’t really know what changing it will
break. <a href="#fnref:matrix" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:fix" role="doc-endnote">
      <p>Full disclosure: matching the aliased and namespace-qualified forms
correctly only landed <em>after</em> 2.0 - the 2.0.x releases had a bug where the
source scan quietly skipped files that referenced a var through its alias,
which is of course the common case. The fix will ship in CIDER 2.1, which
doesn’t have a release date yet. I’m hoping to get back into a rhythm of
cutting a new CIDER release every month or two, so it shouldn’t be a long
wait. <a href="#fnref:fix" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:source" role="doc-endnote">
      <p>“The path of the One ends at the Source.” The Architect was
talking about Zion, but he might as well have been describing every
debugging session that ends with you finally opening the file and reading
the code instead of theorizing about it. <a href="#fnref:source" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Bozhidar Batsov</name></author><category term="posts" /><category term="CIDER 2.0" /><category term="Emacs" /><category term="Clojure" /><category term="CIDER" /><summary type="html"><![CDATA[Next up in the series on the notable changes in CIDER 2.0: cross-references. Or, as most people call the feature, “find usages” - for years the most commonly cited reason to run clojure-lsp alongside (or instead of) CIDER. Let’s talk about why that gap existed and how we finally closed it. Why runtime xref wasn’t enough CIDER has had runtime cross-referencing for a while: the cider/fn-refs op walks the loaded vars in your REPL and reports which functions reference the one at point. It’s a genuinely cool trick - the REPL literally knows your program - but as a “find usages” answer it has three structural problems: It only sees loaded code. Namespaces you haven’t required yet - often most of the codebase - are invisible. It reports functions, not occurrences. Each hit points at the caller’s definition, not the exact call site, and a function that calls yours three times shows up once. It’s JVM-only, so ClojureScript users got nothing. clojure-lsp, by contrast, builds a static index of your whole project with clj-kondo’s analyzer and answers instantly, loaded or not. For occurrence-oriented questions (“show me every place this is used, so I can change all of them”), static analysis is simply the right tool. No amount of runtime cleverness fixes “the code isn’t loaded”. The fix: search the source So CIDER 2.0 does the obvious thing we should have done years ago: xref-find-references (M-?) now finds references by searching the project’s source files on disk. Unloaded code, cljs files, commented-out drafts - if the name occurs in the project, you’ll see the exact occurrence, in the standard xref UI you already use for everything else in Emacs. To borrow the franchise that has been handing programmers debugging metaphors for over two decades now: the runtime is the Matrix, a tidy compiled illusion of your program, and to see every place a thing is really used you sometimes have to unplug and look at the source itself.1 Here’s the difference in one picture - the same query on orchard.misc/require-and-resolve, first in runtime mode, then in source mode: The runtime knows about three callers - and points you at each caller’s definition. The source scan turns up all ten actual occurrences, across five files, including the ones written as misc/require-and-resolve in namespaces the REPL never loaded. That’s the gap, in one screenshot. Now, “search the source” makes it sound like a grep, and I want to be clear that it isn’t a dumb one. Say you’re chasing orchard.misc/require-and-resolve. The search runs in three stages: First CIDER asks the REPL to resolve the symbol at point to its fully qualified name, orchard.misc/require-and-resolve. The REPL is right there on the other end of the wire, so why guess when you can ask? A fast first pass (ripgrep, via Emacs’ own xref-matches-in-files) finds every file that so much as mentions require-and-resolve, purely to narrow the field. Then the Clojure-aware part. For each of those files, CIDER reads its (ns ...) form to learn how that file pulls in orchard.misc - aliased as [orchard.misc :as misc], brought in with :refer [require-and-resolve], or is this orchard.misc itself? - and builds a regexp that matches only the forms that file could legitimately use: the qualified orchard.misc/require-and-resolve, the aliased misc/require-and-resolve, or a bare require-and-resolve where the namespace declaration makes that valid. The requires inside the ns form are excluded, so the import line doesn’t show up as a “usage”.2 Is any of this as smart as clj-kondo’s full analysis? No - it’s ultimately a syntactic search, so an identically named var in another namespace can still sneak through as a false positive. But because it’s ns-aware rather than a blind text match, a bare require-and-resolve in some file that never requires orchard.misc (and has a require-and-resolve of its own) won’t be mistaken for yours. For the daily “where is this used?” question it turns out to be remarkably close to the real thing in practice, it requires zero extra infrastructure, and it composes with what only CIDER has: the running REPL. That composition is configurable via cider-xref-references-mode: source (the default) - occurrences from the project’s files. runtime - the historical loaded-vars behavior. both - source occurrences first, plus the runtime hits the scan can’t see. And there are such hits: references generated by macro expansion leave no textual trace in your source, but the runtime knows about them. Static analysis can’t ever tell you those; your REPL can. (There’s also cider-xref-fn-refs-in-source, C-c C-? s, when you want the source search explicitly, and outside a project the source mode gracefully falls back to the runtime search.) Beyond find usages: the who-* family While closing the gap, we went further and built out a whole family of SLIME-inspired cross-referencing commands under C-c C-w, most of them rendered as expandable trees: cider-who-calls / cider-who-is-called - the call graph, upward and downward. Expand a caller to see its callers; spelunk as deep as you like: cider-who-implements - a protocol’s implementing types (inline defrecord/deftype implementations included) or a multimethod’s dispatch values, each jumping to the implementation’s source. Multimethods are a nice case study in hybrid thinking: the method functions carry no source metadata at runtime, so CIDER locates the defmethod forms by - you guessed it - searching the source. cider-type-protocols / cider-protocols-with-method - the reverse lookups: what does this type implement, and which protocols declare this method? cider-who-macroexpands - a macro’s use sites, found via source search, because macro invocations are expanded away at compile time and the runtime literally cannot see them. Much of this is powered by new ops in cider-nrepl (and Orchard underneath), and much of the inspiration came straight from SLIME and swank-clojure, which offered who-calls back when Clojure itself was barely out of the crib. And here’s the part I love: the whole “go read the source instead of trusting the runtime” instinct was already there in swank-clojure’s implementation. Its who-calls would find candidate callers among the loaded vars, sure, but then it went and read the actual source form of each one off disk and walked the parsed code looking for your symbol, rather than believing whatever the compiled runtime claimed. It was still anchored to loaded code - it never scanned the whole project the way CIDER 2.0 does - but the core idea, that the source on disk is the ground truth and the runtime is just a convenient approximation, predates this release by about fifteen years. Good ideas don’t expire. Sometimes nothing beats revisiting the classics.3 So do you still need clojure-lsp? If you were running clojure-lsp primarily for find-usages - the most common answer I heard when I asked - then CIDER now covers you out of the box. If you use it for project-wide renames, unused-var linting, or editing without a REPL, carry on; those are real strengths of static analysis and CIDER doesn’t try to replicate them. The two continue to work fine side by side, and the new async eldoc even yields politely so LSP-provided docs can compose with CIDER’s. My goal was never to “beat” clojure-lsp - it was to make a freshly installed CIDER answer the questions every Clojure programmer asks a dozen times a day, with no extra moving parts, and with the one advantage nobody else has: a live runtime on the other end of the wire. The full story is in the navigation docs. Keep hacking! Articles in the Series CIDER 2.0: Sky is the Limit Simplifying Session Management in CIDER Stepping Through Macros in CIDER Making CIDER More Discoverable Modernizing CIDER's Completion Closing the Find-Usages Gap in CIDER Sharpening CIDER's Debugging Tools Leveling Up CIDER's ClojureScript Support As Morpheus puts it: “Unfortunately, no one can be told what the Matrix is. You have to see it for yourself.” Same with find-usages, really - I can tell you a var is used in seven places, but until you’ve seen the actual call sites you don’t really know what changing it will break. &#8617; Full disclosure: matching the aliased and namespace-qualified forms correctly only landed after 2.0 - the 2.0.x releases had a bug where the source scan quietly skipped files that referenced a var through its alias, which is of course the common case. The fix will ship in CIDER 2.1, which doesn’t have a release date yet. I’m hoping to get back into a rhythm of cutting a new CIDER release every month or two, so it shouldn’t be a long wait. &#8617; “The path of the One ends at the Source.” The Architect was talking about Zion, but he might as well have been describing every debugging session that ends with you finally opening the file and reading the code instead of theorizing about it. &#8617;]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://metaredux.com/assets/og-image.png" /><media:content medium="image" url="https://metaredux.com/assets/og-image.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry></feed>